
AI Structured Outputs Explained: JSON Mode, Schemas, Function Calling, and the Reliability Gap
AI structured outputs make language-model responses easier for software to parse, display, route, and validate. They solve the shape of an answer—but not automatically its truth. This guide explains the difference, shows where JSON mode and function calling fit, and gives you a practical validation model for real applications.
AI Structured Outputs: The Quick Answer
category, priority, summary, and needs_review with specified data types and allowed values. This makes downstream parsing far more dependable. It does not prove that the values inside those fields are factually correct, supported by the input, authorized, or safe to act on.The cleanest mental model is: a schema is a mold, not a fact-checker. It can require the model to produce a cube instead of a blob. It cannot guarantee that the cube contains the right information. A response can be valid JSON, match every field in your schema, and still contain an invented invoice number, an unsupported diagnosis, a wrong customer status, or a confidently misclassified request.
That distinction matters because structured output often sits at the boundary between probabilistic AI and deterministic software. Once a response looks like ordinary application data, developers may be tempted to trust it like data from a database. The safer approach is to treat it as a typed proposal that must pass progressively stronger checks before it becomes a record, decision, tool call, or external action.
What Are AI Structured Outputs?
A language model naturally generates a sequence of tokens. Left unconstrained, it can answer with prose, a list, Markdown, a code block, partial JSON, or a mixture of all five. Humans can often interpret those variations. Software cannot safely assume that the field it needs will appear in the right place, use the right type, or even exist.
Structured output adds a contract for the response shape. The contract might say that the result must be an object with a required sentiment field chosen from three values, a numerical confidence field, an array of evidence strings, and a Boolean needs_human_review field. Modern model APIs can use a supported subset of JSON Schema to guide or constrain generation so the result is syntactically valid and adheres to the requested structure.
That makes structured output useful wherever an AI response must cross into conventional software: filling a form, rendering a UI, classifying support tickets, extracting line items, generating a workflow plan, passing data to another agent, or storing a result for later analysis. It replaces fragile instructions such as “return only JSON and do not add commentary” with an explicit interface.
The key word is interface. Structured output does not turn a language model into a database query engine, rules engine, or source of record. It gives those systems a predictable way to receive the model’s proposal. The receiving application still owns validation and consequences.
A small example
Imagine a customer email that says, “My order arrived damaged and I need a replacement before Friday.” A free-form assistant might write a sympathetic paragraph. A structured-output classifier could return an object like this:
{
  "intent": "replacement_request",
  "urgency": "high",
  "order_id": null,
  "requested_deadline": "Friday",
  "needs_human_review": true,
  "reason": "No order identifier was present in the message."
}
The shape helps the application route the request. Yet the application must still verify that “Friday” can be converted to a real date, that the customer is entitled to a replacement, that an order can be identified, and that the model did not infer details absent from the email. Good structure creates a reliable starting point for those checks.
Raw Text, JSON Mode, Structured Outputs, and Function Calling
These terms are often blended together because they can all involve JSON. They solve different problems. The official OpenAI structured outputs guide distinguishes schema-shaped responses from function calling, and the Gemini documentation makes the same primary-use distinction: structured outputs format a final answer, while function calling helps a model request an intermediate action or data lookup.
| Mode | What it guarantees | Best use | What it does not guarantee |
|---|---|---|---|
| Free-form text | No machine-readable contract beyond normal language generation | Explanations, drafting, brainstorming, conversational answers | Stable fields, parseability, consistent formatting, factual accuracy |
| Prompted JSON | Nothing formal; the prompt merely asks for JSON | Experiments and models without a native structured mode | Valid JSON, schema adherence, no extra prose, correct values |
| JSON mode | Valid JSON at the syntax level | Flexible objects where exact schema enforcement is unavailable or unnecessary | Required keys, exact types, allowed values, semantic correctness |
| Structured output | Valid JSON that adheres to a supported schema | Extraction, classification, UI data, workflow state, agent handoffs | Truth, evidence, authorization, business-rule validity, completeness of the source |
| Function or tool calling | A structured request naming a tool and proposed arguments | Retrieving data or asking the application to perform an action | That the tool should run, the arguments are safe, or the action is authorized |
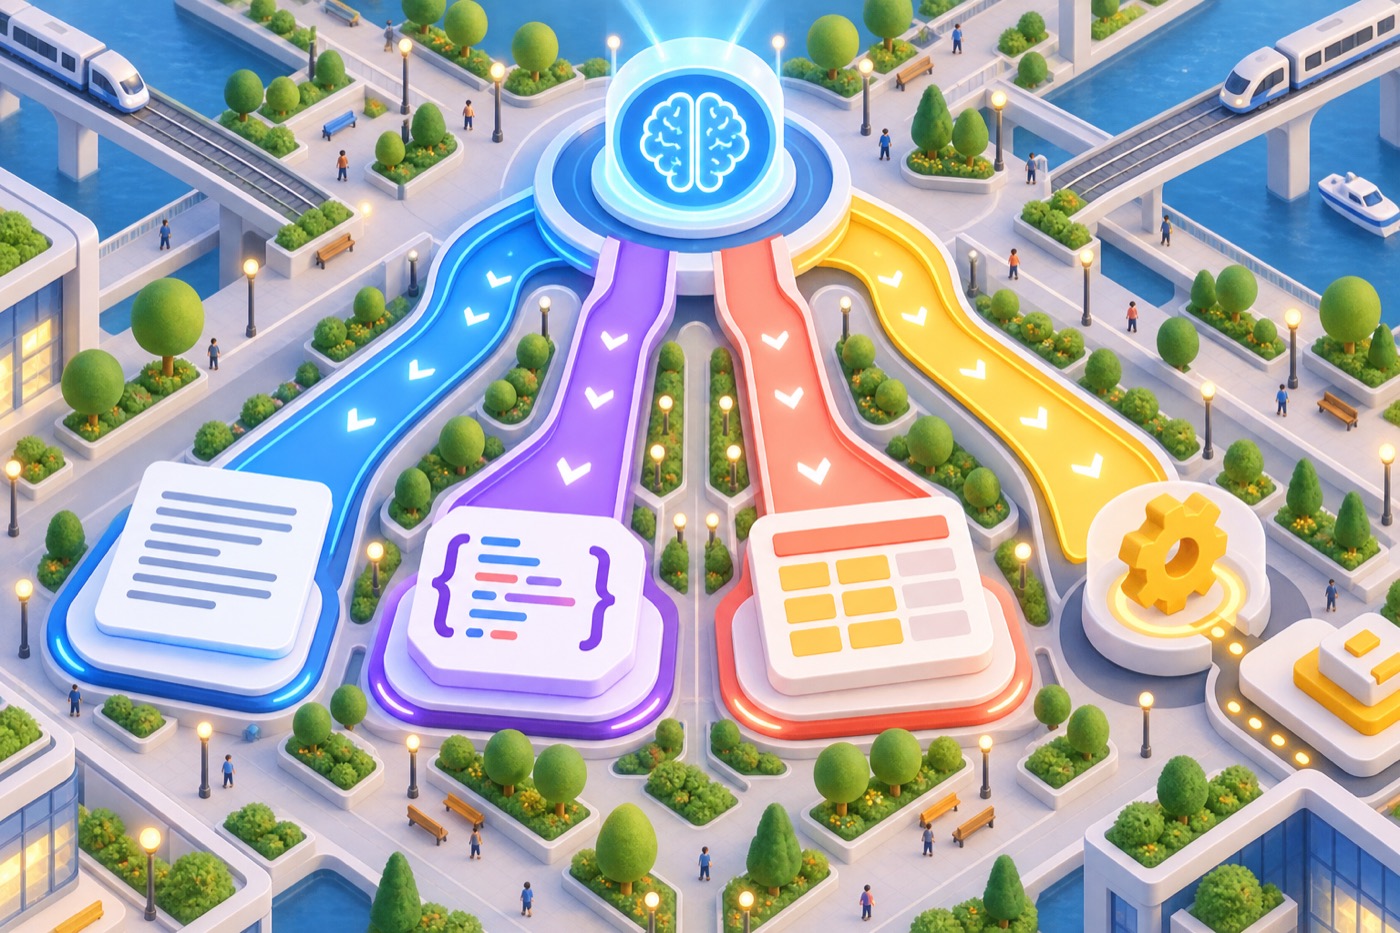
One model can produce several kinds of output. Choose the mode according to what the receiving system must do next.
Why JSON mode is not the same as a schema
Valid JSON only means the braces, quotes, commas, arrays, and primitive values can be parsed. A model could return {"banana":42} when your application expected a support-ticket classification. The document is valid JSON and useless to the workflow. Schema adherence adds field names, types, required properties, enums, nesting rules, and other supported constraints.
Why function calling is not merely structured extraction
A function call is a proposal to cross an execution boundary. The model might request get_order_status with an order identifier, or cancel_subscription with a customer ID. The application or tool runtime executes the operation and returns a result. Structured output, by contrast, can simply format the model’s final answer for a UI or storage layer. Some APIs use the same schema machinery for both, but the consequence is different: one shapes data; the other may initiate behavior.
If you need a deeper explanation of agents that can plan and use external capabilities, read AI agent tool use explained and AI agents vs. agentic AI. The important connection is that every tool call is structured, but not every structured response is a tool call.
How Schema-Constrained AI Output Works
At a practical level, your application sends three things to the model service: the task, the source material or context, and a schema describing the desired response. The provider translates that schema into guidance and, on supported models, constraints over which tokens can legally appear as the response is generated.
- Define the job. State what should be extracted, classified, summarized, or decided. A schema cannot rescue an ambiguous task definition.
- Define the shape. Specify objects, arrays, strings, numbers, Booleans, nullability, required fields, and enums. Keep the schema as small as the downstream decision allows.
- Generate under constraints. The model produces tokens while the provider prevents disallowed structural paths. Exact behavior and the supported JSON Schema subset vary by provider and model.
- Parse and validate locally. The application deserializes the result into a typed object and re-validates it. Native schema adherence is not a reason to remove local checks.
- Apply domain checks. Verify dates, identifiers, totals, relationships, source evidence, policy rules, and any invariants the schema cannot express.
- Choose the consequence. Accept, reject, retry, route to review, or request missing information. High-impact outputs should not silently fall through to action.
Constrained generation can be more reliable than asking the model politely to follow a format because invalid structural tokens are blocked rather than merely discouraged. However, providers generally support only part of the full JSON Schema standard, and supported features change. Google documents that its structured mode supports a subset and warns that very large or deeply nested schemas may be rejected. Amazon Bedrock’s documentation similarly lists supported and unsupported schema features for its runtime.
What schema descriptions really do
A field description is not decoration. It is part of the model’s instruction context. Compare a vague field such as status with a precise one: “The customer-visible fulfillment state supported by the cited order record; never infer from tone.” The second description narrows the intended meaning and tells the model which evidence matters.
Even then, descriptions remain instructions to a probabilistic system. If your application needs a hard rule—“refund amount must not exceed captured payment”—implement it in deterministic code against authoritative records. Use the schema to transport the candidate value, not to enforce the financial policy.
The Reliability Gap: Valid Shape Is Not Valid Meaning
The most dangerous structured-output mistake is believing that a parseable, schema-valid object is automatically trustworthy. It looks like normal application data. It passes type checks. It may even contain a confidence score. None of those properties prove that the model read the source correctly or that the source supported the conclusion.
The Gemini documentation states this directly: syntactically correct JSON does not guarantee semantically correct values, so applications should validate final outputs and handle schema-compliant but incorrect results. This is not a minor caveat. It defines the boundary of what structured output can solve.
Five examples of perfectly shaped wrong answers
- Invented identifier: the schema requires an invoice ID, so the model supplies a plausible-looking one even though the document is unreadable.
- False enum certainty: the allowed values are
approvedordenied, but the evidence is incomplete. Without anunknownoption, the model must choose a false certainty. - Wrong date interpretation: a valid ISO date is returned, but “next Friday” was resolved against the wrong timezone or reference date.
- Correct type, wrong unit: a numeric amount is extracted as 1,200 while the source meant 1,200 cents, not 1,200 dollars.
- Unsupported confidence: the schema asks for a number from zero to one, so the model produces 0.94. The number looks scientific but may not be calibrated against real outcomes.
null is a legitimate state, model it explicitly. Otherwise the schema can turn uncertainty into fabricated precision.This is closely related to the wider problem in AI hallucinations. Structure changes how an error is packaged; it does not remove the error. A wrong paragraph may invite skepticism. A wrong typed object may travel through several systems before anyone notices.
A Four-Layer Validation Model for Structured AI Responses
A dependable system validates structured AI output in layers. Each layer answers a different question. Combining them is more useful than searching for a single “reliability score.”
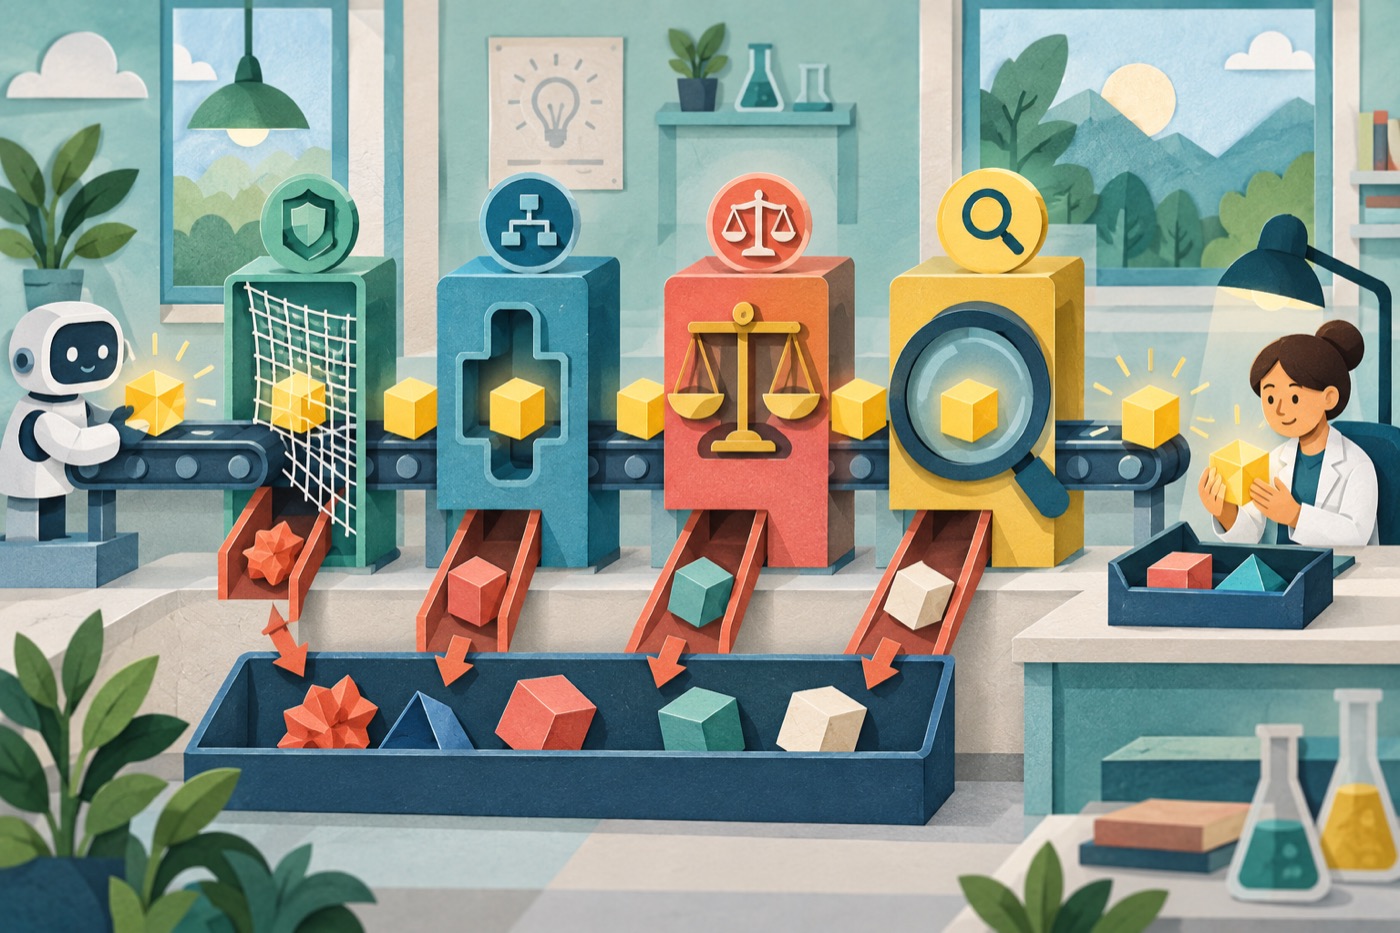
A schema gate is one checkpoint in a broader validation line, not the finish line.
Layer 1: syntax and transport
Can the response be parsed? Did the request finish, or was it truncated, refused, timed out, or interrupted? Is the content type what the client expected? Did streaming finish cleanly? Even native structured modes need explicit handling for refusals and incomplete responses rather than pretending every request returns a normal object.
Layer 2: schema and type validation
Does the object match the exact schema version your application expects? Re-validate locally with the same source-of-truth type definition used by the application. Reject extra properties when they would hide drift. Treat schema versions like API versions, because renaming a field or changing an enum can break consumers even when the model behaves correctly.
Layer 3: domain and business rules
Now test rules the schema cannot fully express. A start date must precede an end date. Line items should reconcile to a total within a defined tolerance. A customer ID must exist. A selected plan must be available in the customer’s region. A medical code must be compatible with the source note and should never be auto-applied solely because a model returned it.
Layer 4: evidence, authority, and consequence
Verify claims against authoritative data. Require citations or source spans when extraction traceability matters. Confirm that the requesting user and acting service are authorized for the proposed operation. Decide whether the consequence is low enough to automate, or whether the result should become a review task. This is where structured data becomes an accountable decision rather than a convenient guess.
| Failure | Best detector | Recommended response | Why retry alone is insufficient |
|---|---|---|---|
| Malformed or incomplete JSON | Parser and completion status | Retry with bounded attempts or use native schema mode | A retry can fix transport or formatting, but not meaning |
| Schema mismatch | Local schema validator | Reject, log, and retry with the validation error if appropriate | Repeated failure may indicate unsupported complexity or a bad schema |
| Impossible value | Deterministic business rule | Reject or route to review | The model may repeat a plausible but impossible value |
| Unsupported claim | Source-span check or authoritative lookup | Mark unknown, request evidence, or escalate | Formatting feedback does not supply missing evidence |
| Unauthorized action | External policy and identity layer | Block or request scoped approval | The acting model must not grant itself authority |
| Low-confidence high-impact case | Risk policy plus human review | Queue an evidence-rich review | A second model answer is not independent authorization |
For production systems, log which layer rejected the output. A single “model failed” metric hides the information needed to improve the prompt, schema, data source, validator, or workflow. The failure taxonomy should distinguish parse failure, schema failure, domain-rule failure, evidence failure, policy denial, and human rejection.
Where AI Structured Outputs Are Most Useful
The best use cases have a clear source, a bounded task, an explicit downstream consumer, and a validation path. Structured output is especially valuable when the alternative is brittle parsing of free-form prose.
Document extraction
Extract names, dates, clauses, totals, product codes, or obligations from documents. Include source spans or page references when auditability matters. Keep “not present” distinct from “inferred.” For financial or legal workflows, reconcile extracted values against authoritative records and route ambiguous documents to review.
Classification and routing
Classify support tickets, feedback, incidents, or content into a small set of operational categories. Enums are helpful because they prevent new labels from appearing silently. Add an unknown or needs_review path so difficult cases do not become forced guesses.
UI generation and form filling
A structured response can populate cards, timelines, comparison rows, or form fields. Keep rendering logic deterministic: the model supplies content and choices within an allowed schema; the application controls executable code, layout boundaries, sanitization, and accessibility.
Workflow state and agent handoffs
One agent or step can return a typed task state for the next step: objective, completed work, open questions, evidence references, risk flags, and required approvals. This reduces ambiguity between components. Pair it with the context practices in context engineering for AI agents, because a perfect handoff schema cannot compensate for missing or unauthorized context.
Evaluation records
Ask an evaluator to return a rubric outcome with separate fields for criteria, evidence, pass/fail status, and review notes. Do not treat model-generated scores as ground truth. Calibrate them against human-labeled examples and measure disagreement. The AI hallucination evaluation checklist shows how to test answers before users trust them.
When not to use a rigid schema
Free-form prose remains better for creative ideation, nuanced explanation, exploratory analysis, and situations where you do not yet understand the dimensions of the answer. A premature schema can narrow the model into categories that reflect your assumptions rather than the problem. Start with exploratory samples, discover the stable fields, and introduce structure only when a consumer truly needs it.
How to Design a Good JSON Schema for an AI Model
A good schema is small, explicit, versioned, and aligned with a real decision. It gives uncertainty somewhere honest to go. It does not ask the model to invent operational facts merely to satisfy required fields.
1. Begin with the consumer
List exactly what the next system needs. If a ticket router uses only category, severity, and review status, do not ask the model for fifteen decorative fields. Every extra field consumes attention, adds tokens, creates another place for error, and increases the chance that future code begins depending on an unreliable value.
2. Separate extraction from interpretation
Keep direct evidence apart from model judgment. For example, use quoted_deadline_text for the words found in the document, normalized_deadline for the interpreted date, and normalization_status for success, ambiguity, or missing context. This makes it possible to review the transformation rather than receiving only a polished conclusion.
3. Model uncertainty deliberately
Use nullable fields, explicit unknown states, ambiguity flags, and arrays that may be empty. Avoid asking for a confidence number unless you have a calibration method and a policy that uses it responsibly. A categorical reason such as “missing source evidence” can be more actionable than an invented decimal.
4. Prefer enums for operational decisions
Enums stop label drift. Define them narrowly and document each option. Include a fallback category. Do not put two different decisions into one enum—for example, mixing content category with escalation status. Separate fields are easier to validate and analyze.
5. Add descriptions that constrain meaning
Describe evidence requirements, units, reference times, and forbidden inference. “Total amount” is weaker than “Total payable amount printed on the invoice, in the currency shown; return null when not visible.” Descriptions should guide the model, while code enforces hard rules.
6. Keep nesting shallow
Deeply nested schemas are harder for models, developers, logs, and review tools. If a result becomes a miniature database, split the task into stages. Extract the core record first, validate it, then derive secondary structures in deterministic code or a second bounded model call.
7. Version the contract
Add an application-level schema version or bind the validator to a deployed version. Test old and new consumers during migrations. Save representative fixtures and adversarial examples. A prompt change, model change, schema change, and upstream document change can all alter outcomes even if the endpoint stays the same.
8. Refuse unsupported work cleanly
Design an explicit result for refusal, missing input, or insufficient evidence rather than forcing the normal success object. Your application should know the difference between “the answer is empty” and “the model could not safely answer.”
Provider Support and Portability
OpenAI, Google, and Amazon Bedrock all document schema-constrained structured output, but their request shapes, supported models, supported JSON Schema features, streaming behavior, refusals, and tool combinations differ. Treat the full JSON Schema specification as a vocabulary, not proof that every keyword works everywhere.
For portability, keep one provider-neutral domain model in your application and write thin adapters for each model API. Generate provider schemas from the same source types when possible. Maintain a compatibility test suite that exercises required fields, enums, nulls, arrays, nesting, refusals, incomplete outputs, and deliberately ambiguous inputs.
Do not silently weaken validation when a provider lacks a schema feature. Move the constraint into application code and document the shift. For example, if numeric bounds are unsupported, still accept a numeric field at generation time but enforce the range after parsing. The same rule applies to string length, cross-field relationships, uniqueness, and external references.
Also test behavior rather than relying only on capability tables. A provider may guarantee schema adherence while different models vary in how well they choose correct values, respect field descriptions, use null, or avoid hallucinated evidence. Structural conformance is binary; task quality is empirical.
Interactive Decision Helper: Which Output Mode Fits?
Use this lightweight helper to choose a starting pattern. It does not replace provider documentation or a risk review; it clarifies whether your main need is human-readable prose, parseable data, an exact response contract, or a controlled action request.
A common architecture uses more than one mode in the same turn. The model may request a tool through function calling, the application may execute a read-only lookup, and the model may then return a schema-constrained final answer for a UI. Keep each boundary explicit so logs show what was requested, what ran, what data came back, and what final result was accepted.
A Production-Minded Implementation Blueprint
You do not need an elaborate platform to start. You need a small contract, a representative test set, deterministic validation, and a clear fallback. Add complexity when observed failures justify it.
- Write the decision statement. Define what the structured result will influence and what it must never do automatically.
- Collect representative inputs. Include clean cases, incomplete cases, conflicting evidence, unusual formatting, adversarial text, and genuinely unanswerable examples.
- Design the smallest schema. Include unknown and review states. Separate extracted evidence from interpretation.
- Create a typed local model. Use a validation library in your application language and generate the API schema from that source when practical.
- Call a supported structured mode. Handle completion, refusal, truncation, timeout, and provider errors explicitly.
- Re-validate locally. Treat the provider response as untrusted input at the network boundary.
- Apply deterministic checks. Enforce cross-field rules, units, date logic, identifiers, totals, uniqueness, and reference-data lookups.
- Verify evidence. Require source spans or citations for claims that must be traceable. Confirm that cited text actually supports each value.
- Route by consequence. Auto-accept low-impact, well-validated cases; queue ambiguous or high-impact cases with the evidence a reviewer needs.
- Measure outcomes. Track parse success, schema success, domain-rule failure, evidence failure, reviewer disagreement, false acceptance, latency, cost, and drift by model and schema version.
A simple control-flow pattern
result = model.generate(task, source, schema)

if result.refused or result.incomplete:
    return route_to_fallback(result.status)

typed = schema_validator.parse(result.output)
domain_errors = check_business_rules(typed)
evidence_errors = verify_against_source(typed, source)

if domain_errors or evidence_errors:
    return review_queue(typed, domain_errors, evidence_errors)

if consequence_is_high(typed):
    return approval_queue(typed)

return accept(typed)
Notice what is missing: the model does not approve its own output, grant its own permissions, or decide that validation can be skipped. It proposes. Deterministic systems and accountable people decide what happens next.
Retries, repair, and fallbacks
A retry is appropriate for a transient failure, incomplete generation, or fixable validation error. Make retries bounded, record why they happened, and avoid feeding an endless loop with the same impossible task. If the source lacks a required fact, no number of retries can recover it. The correct result is missing information or human review.
Fallbacks can include a simpler schema, a different model, deterministic extraction, asking the user for missing information, or returning a safe partial result. A fallback should reduce uncertainty or impact, not merely produce something that passes the parser.
Testing that matters
Measure more than schema-pass rate. Build a golden dataset with expected values and acceptable alternatives. Include negative cases in which the correct behavior is null, unknown, refusal, or escalation. Track field-level precision and recall for extraction, classification confusion, evidence support, and reviewer disagreement. If a model returns 100 percent valid JSON and 12 percent wrong values, your parser dashboard is green while your product is failing.
Use the deployment practices in the AI agent deployment pipeline: version changes, run evaluations, release gradually, trace failures, and keep a rollback path. Even a non-agentic structured-output service benefits from the same discipline.
Common Misconceptions
“The API guarantees 100 percent reliability.”
A provider may guarantee adherence to a supported schema for a completed, non-refused response. That is structural reliability. It is not a guarantee of correct extraction, correct classification, truthful content, or successful business outcomes.
“If the output validates, we can store it as truth.”
Validation means the object fits rules you defined. Store provenance, model and schema versions, source references, validation status, and reviewer outcome when the record may later be audited. Separate model-derived data from authoritative system-of-record fields.
“A confidence field tells us when the model is right.”
Not automatically. A requested confidence number may be another generated value. Use empirical calibration against labeled outcomes before assigning thresholds. Even calibrated confidence does not replace authorization or impact-based review.
“Function calling means the model executes the function.”
In the common client-side pattern, the model proposes a function name and arguments. Your application decides whether and how to run it, then returns the result. Some platforms offer server-side tools, but the security principle remains: execution and policy must be controlled by the surrounding system.
“A bigger schema captures more value.”
A bigger schema often creates more failure surfaces. Include fields because a consumer needs them, not because the model can fill them. Derive deterministic fields in code and split large tasks into testable stages.
Final Takeaway: Structure the Response, Validate the Meaning
AI structured outputs are one of the most useful bridges between language models and dependable software. They replace prompt-only formatting tricks with explicit contracts. They make responses easier to parse, test, render, route, compare, and monitor. They also make errors look more like ordinary data, which is why the reliability boundary must be understood clearly.
Use free-form text when a person needs explanation. Use JSON mode when parseable JSON is enough and exact fields can remain flexible. Use schema-constrained output when an application needs a stable response contract. Use function calling when the model must ask your system to retrieve information or perform an action. In every case, validate according to consequence.
The mature pattern is not “model returns JSON, therefore the workflow is safe.” It is: model returns a typed proposal; the application validates structure; deterministic code checks domain rules; authoritative sources verify evidence; policy checks authority; and a person reviews the cases whose impact or ambiguity demands judgment.
FAQ About AI Structured Outputs
What are AI structured outputs in simple terms?
They are AI responses forced into a predictable machine-readable shape, usually defined with JSON Schema. The schema can require specific fields, types, and allowed values so an application can parse the response reliably.
What is the difference between JSON mode and structured outputs?
JSON mode ensures the response is valid JSON. Structured outputs go further by requiring the JSON to match a defined schema. Neither one guarantees that the values are factually or semantically correct.
Are structured outputs the same as function calling?
No. Structured outputs usually shape the model’s final response. Function calling gives the model a structured way to request that your application use a tool or function. Both may use JSON Schema, but function calling can lead to an external action.
Can schema-valid AI output still hallucinate?
Yes. A model can produce an object that perfectly matches the schema while inventing an identifier, misreading a date, choosing the wrong category, or asserting a value unsupported by the source. Validate evidence and business rules separately.
Should I validate structured output in my application?
Yes. Re-validate the response locally, check domain rules and authoritative records, handle refusals and incomplete outputs, and route ambiguous or high-impact cases to review. Treat the response as untrusted network input.
How should a schema represent uncertainty?
Allow null or explicit values such as unknown, ambiguous, missing evidence, and needs review. Do not force a binary answer when the source may not support one. Keep extracted evidence separate from model interpretation.
When should I avoid structured outputs?
A rigid schema may be a poor fit for brainstorming, creative writing, exploratory analysis, or a new problem whose stable dimensions are not yet understood. Use free-form samples first, then add structure when a downstream consumer needs it.
Do all model providers support the same JSON Schema features?
No. Providers and models support different subsets and request formats. Maintain a provider-neutral domain type, adapter tests, and local validation. Check current official documentation before depending on a particular schema feature.
What metrics should I track in production?
Track completion and refusal rates, parse and schema success, field-level correctness, domain-rule failures, evidence failures, reviewer disagreement, false acceptance, latency, cost, and drift by model, prompt, and schema version.
