
AI Agent Checkpointing: How to Save State, Resume Runs, and Recover Safely
AI agent checkpointing turns a fragile long-running task into a recoverable workflow. This guide explains what a checkpoint must contain, where to create one, how to resume without repeating external actions, and how to test the recovery path before production discovers the gaps for you.
AI Agent Checkpointing: The Quick Answer
AI agent checkpointing is the practice of saving enough durable workflow state at a known boundary so an interrupted agent can continue from a safe point instead of starting from the beginning. A useful checkpoint does not merely store the chat transcript. It records where the workflow is, which inputs and outputs were validated, which tool effects were confirmed, what approvals were granted, which code and prompt versions produced the state, and what action is safe to attempt next.
The distinction matters because an agent can fail after it has changed the outside world. Imagine a research-and-publishing agent that has gathered sources, generated a draft, uploaded an image, created a CMS post, and then loses its process before receiving the CMS response. Restarting from the first prompt wastes work. Blindly rerunning the final tool call may create a duplicate post. Resuming safely requires both a checkpoint and a record of external effects.
Frameworks increasingly expose this concept directly. LangGraph persistence separates thread-scoped graph checkpoints from cross-thread stores. Microsoft Agent Framework checkpoints can capture executor state, pending messages, requests, responses, and shared state at workflow boundaries. Durable execution systems such as Temporal rebuild progress from an event history. The implementations differ, but the engineering questions are the same: what is authoritative, what can be replayed, and what must never run twice?
Why Long-Running AI Agents Need Checkpoints
A short model call can be retried as one unit. A long-running agent is closer to a distributed workflow. It may wait for a human, call several APIs, stream partial results, delegate to another agent, create files, pause overnight, or survive a deployment. The longer the run and the more systems it touches, the less reasonable “start again” becomes.
Agents are especially vulnerable because their execution is partly nondeterministic. The same model, input, and tool descriptions may produce a different plan on a later attempt. Even a deterministic orchestrator can see new data when it retries. A search index changes, an inventory count moves, a permission expires, or a human edits the target record. Recovery therefore cannot mean asking the model to remember what it probably did. The system needs durable facts.
This is the missing layer between several familiar reliability patterns. Durable AI workflows explain retries and long-lived execution. AI agent idempotency prevents duplicate actions. The AI agent saga pattern coordinates compensating actions when a multi-step workflow fails. Checkpointing binds those ideas to a precise resume point.
It is also different from memory. Agent memory helps a system recall preferences, facts, or prior conversations. A checkpoint is execution state for one workflow lineage. Mixing the two creates dangerous ambiguity. A memory store may say that a customer prefers email, but it should not be the only record proving that a refund step completed. LangGraph’s documentation makes this separation explicit: checkpointers hold thread state, while stores hold application-defined information across threads.
What an AI Agent Checkpoint Must Save
The correct checkpoint is neither “everything in RAM” nor “the last message.” It is the smallest durable package that lets a compatible runtime make the next decision without guessing. The package should be typed, versioned, integrity-protected, and understandable without replaying private model reasoning.
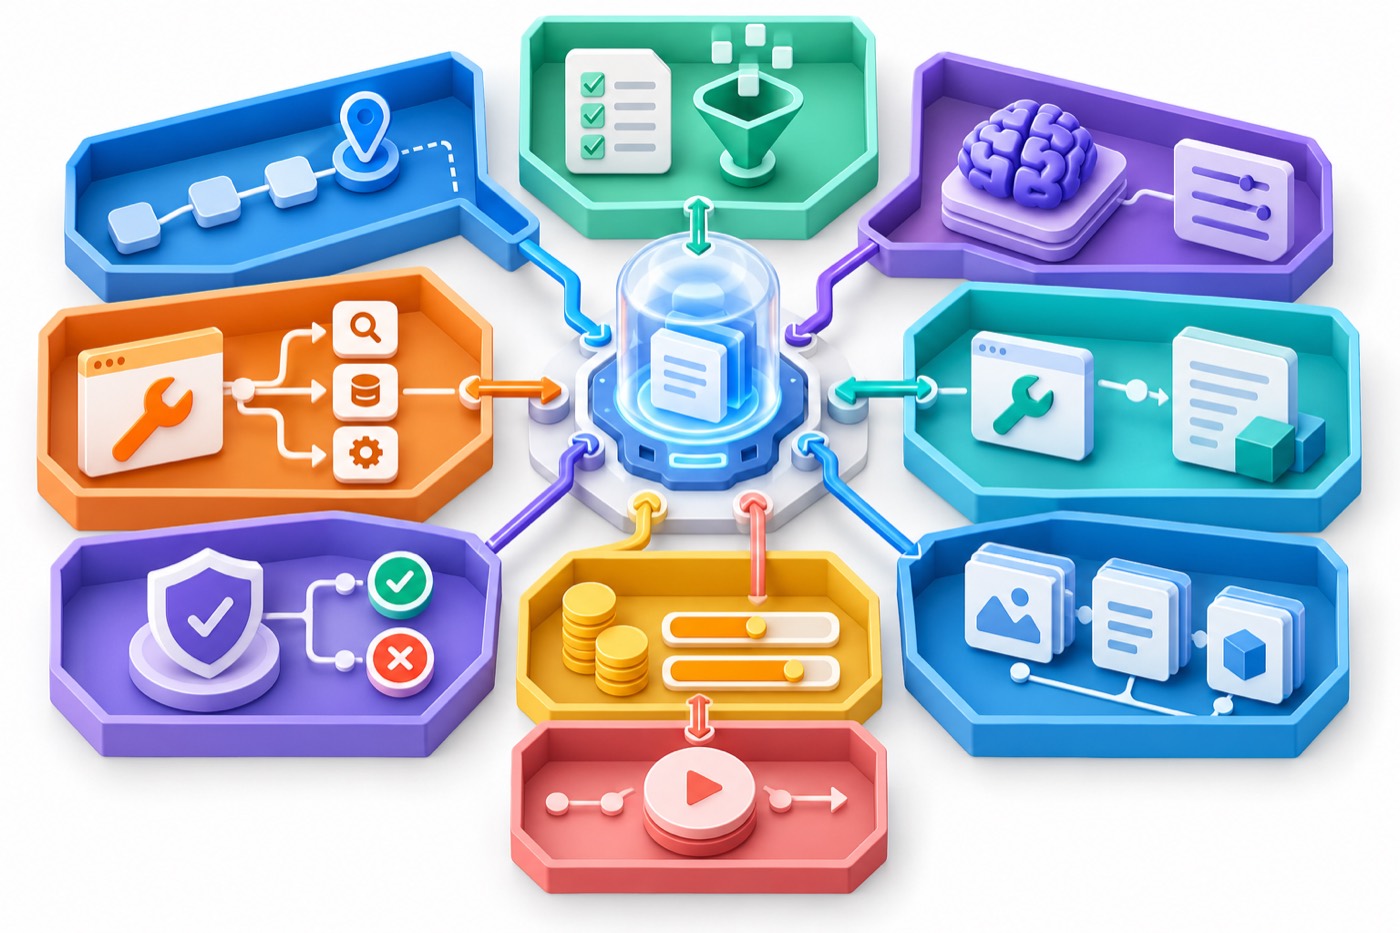
A useful checkpoint is a structured recovery contract, not a screenshot of the agent’s conversation.
| Checkpoint field | Why it is needed | Failure if omitted |
|---|---|---|
| Workflow and lineage IDs | Identify the logical job, current run, parent branch, tenant, and ownership boundary. | A resumed worker can attach state to the wrong job or create a parallel run. |
| State-machine position | Record the last committed step and the next eligible transitions. | The model guesses what happened from prose and may skip or repeat a step. |
| Validated input snapshot | Preserve the approved request, normalized parameters, policy context, and preconditions. | Recovery silently uses changed input or loses the user’s approved scope. |
| Model, prompt, tool, and schema versions | Explain which executable contract produced the state and whether the new runtime is compatible. | A new deployment interprets old state differently or replays with changed behavior. |
| Tool intent and idempotency key | Name the logical external action consistently across attempts. | A retry generates a new identity and creates a duplicate effect. |
| Tool receipt and reconciliation status | Store downstream IDs, result hashes, timestamps, and confirmed postconditions. | The workflow cannot distinguish “call failed” from “response was lost.” |
| Approval and authorization state | Preserve who approved what, under which policy and expiration. | Recovery bypasses a gate or relies on stale authority. |
| Artifacts and provenance | Reference generated files, source lists, evaluations, and immutable content hashes. | The run recomputes expensive output or uses an unverified replacement. |
| Budgets and stop conditions | Carry token, time, cost, retry, and step limits into the resumed run. | Restarting resets safety limits and enables an unbounded loop. |
| Pending work and next safe action | Declare what is awaiting input and which transition may legally run next. | Two workers claim the same task or the agent advances before reconciliation. |
Do not serialize secrets into a checkpoint simply because they were present in memory. Save references to secret-manager entries and reacquire short-lived credentials during resume. Treat checkpoint storage as trusted application infrastructure. Microsoft’s checkpoint documentation warns that stored state is a trust boundary and that deserializing tampered objects can be dangerous. Encryption at rest, scoped access, tenant isolation, integrity checks, retention limits, and audit logs belong in the baseline design.
Likewise, avoid storing raw chain-of-thought. It is unnecessary for recovery and creates privacy, security, and product risks. Save explicit decisions, evidence references, tool arguments, validator results, and concise rationales that operators can inspect. The recovery contract should describe what the system decided and verified, not expose hidden internal reasoning.
Where to Place Checkpoint Boundaries
Checkpoint too rarely and a crash discards expensive work. Checkpoint after every token and storage, latency, and operational complexity explode. Good boundaries follow semantic commits: points where the system has a coherent state, knows the result of important work, and can state what is safe next.
Before a high-impact external action
Write the intended operation, stable idempotency key, validated arguments, authorization, and expected postcondition before calling the tool. This is an intent checkpoint. If the process dies during the call, recovery can query the downstream system using the same identity rather than inventing a new request.
After the effect is confirmed
Persist the receipt and advance the workflow atomically, or as close to atomically as the architecture permits. The state should not say “step complete” until the system can prove the external postcondition. A model’s natural-language claim that it sent the message is not proof; the mail provider’s message ID and status are.
After expensive deterministic work
Save validated extraction results, embeddings, compiled plans, generated artifacts, or evaluation reports when recomputation would be costly. Store large artifacts in object storage and place immutable pointers plus hashes in the checkpoint. Do not turn the transactional checkpoint row into a binary warehouse.
At every human-interaction boundary
Pause only after the pending question, approval payload, policy version, and allowed responses have been saved. On resume, verify the response belongs to the correct request and is still timely. Microsoft’s human-in-the-loop workflow guidance notes that pending requests can be checkpointed and re-emitted on restore. This is safer than keeping a live process waiting in memory.
At branch and handoff boundaries
When one agent delegates to another, record the handoff contract: input artifact, expected output schema, deadline, permissions, and ownership. A shared transcript is not enough. The receiving worker should be able to reject an incompatible or incomplete handoff rather than continuing with assumptions.
After validation, not before it
A checkpoint can preserve a bad result perfectly. If an extraction, model output, or tool response requires validation, do that first and mark the evidence. When confidence is insufficient, checkpoint the uncertain state as “needs review” rather than “completed.” This small distinction prevents poisoned state from becoming the foundation for every later step.
A Production Checkpointing Architecture
A practical design separates orchestration state, external effects, and large artifacts. The workflow state store answers “where are we?” The effect ledger answers “what may have happened outside?” The artifact store answers “where is the evidence or output?” Traces answer “how did the attempt behave?” Keeping those roles distinct makes recovery easier to reason about.
| Component | Authoritative responsibility | Typical implementation |
|---|---|---|
| Workflow state store | Versioned state machine, checkpoint sequence, ownership lease, pending transitions. | Transactional database or framework checkpointer backed by PostgreSQL, Cosmos DB, or another durable store. |
| Effect ledger | Intent, idempotency key, request fingerprint, attempt status, downstream receipt, reconciliation result. | Append-oriented table keyed by workflow and logical operation. |
| Artifact store | Large immutable inputs, outputs, reports, source snapshots, and file hashes. | Object storage with retention, access control, and content addressing. |
| Queue or scheduler | Delivery of eligible work, visibility timeout, retries, and dead-letter routing. | Durable queue or workflow engine; never the sole source of truth for progress. |
| Lease manager | Prevent two workers from advancing the same checkpoint concurrently. | Compare-and-swap version, row lock, lease token, or workflow-engine ownership. |
| Policy and approval store | Current policy, decision evidence, approver identity, scope, and expiration. | Dedicated authorization service or strongly controlled database records. |
| Observability pipeline | Attempts, latency, failure classes, recovery outcomes, and operator actions. | Structured logs, metrics, and traces linked by workflow and checkpoint IDs. |
Framework-native checkpointers are useful, but understand their boundary. An in-memory saver can support development and local time travel while still losing everything on restart. LangGraph explicitly recommends a persistent checkpointer for production and warns that checkpoint history can grow without retention. Microsoft notes that some server-side session state may not be captured by workflow checkpoints. A framework feature is therefore a starting point, not proof that every dependency is recoverable.
Durable workflow engines take a different approach. Temporal records event history and uses replay to reconstruct workflow state, while isolating external work in activities. AWS Step Functions provides durable, auditable state-machine execution and is often used for long-running coordination. These systems reduce custom recovery code, but they still require deterministic workflow logic, stable activity identities, safe retries, and careful treatment of external side effects.
Your architecture should also link checkpointing to AI agent observability. Traces explain attempts; checkpoints define committed state. A trace span can show that a tool call started, but unless the result is reconciled and committed, it should not advance the recovery state. Conversely, a checkpoint without trace links makes incident investigation needlessly opaque.
How to Implement AI Agent Checkpointing Step by Step
1. Define the workflow as explicit states
Start with a finite set of business states rather than an open-ended conversation loop. For a content workflow, states might be brief_validated, research_complete, draft_validated, assets_uploaded, publish_intent_recorded, and published. Define which events move the workflow and which invariants must hold at each boundary.
2. Create a versioned checkpoint envelope
Use a typed schema with an explicit version. Include workflow ID, run lineage, checkpoint number, state, input hash, artifact pointers, effect references, approvals, budgets, timestamps, and the next permitted actions. Add an integrity field or authenticated storage layer. Reject checkpoints from the wrong tenant or unsupported schema.
Checkpoint {
  schema_version: 3
  workflow_id: "wf_..."
  lineage_id: "run_..."
  sequence: 14
  state: "assets_uploaded"
  input_hash: "sha256:..."
  plan_version: "publish-flow@5"
  prompt_version: "writer@12"
  model_contract: "structured-draft-v2"
  artifacts: [{uri, sha256, media_type}]
  effects: [{operation_id, intent, status, receipt_id}]
  approvals: [{gate, actor, scope, expires_at}]
  budget: {attempts_left, time_left_ms, cost_limit}
  next_actions: ["record_publish_intent"]
}
3. Use compare-and-swap on every transition
A worker reads checkpoint 14, performs eligible work, and attempts to commit checkpoint 15 only if the current version is still 14 and its lease remains valid. If another worker has already advanced the workflow, the write fails. The losing worker discards its local plan and reloads. This optimistic-concurrency rule blocks a common failure: two recovered workers both believing they own the next step.
4. Record intent before mutation
For each external action, create an effect record with a stable operation ID and request fingerprint before calling the service. The downstream idempotency key must remain the same across retries. AWS’s guidance on idempotent APIs explains why caller-provided request identifiers let a service recognize repeated intent.
5. Reconcile ambiguous outcomes
If the call times out, do not mark it failed and immediately issue a new operation. Move it to unknown. Query by the stable key, downstream receipt, or expected postcondition. If the target confirms completion, commit the receipt. If it confirms absence, retry the same logical operation. If it cannot answer, pause or escalate according to impact.
6. Commit verified results
Normalize and validate tool output, save any large artifact separately, append the receipt, and advance the checkpoint. For model-generated data, validate schema and business rules before committing. If a human must review, save a review task and checkpoint the pending gate.
7. Resume through a deterministic dispatcher
On startup, load the latest compatible checkpoint, acquire ownership, inspect unresolved effects, refresh short-lived credentials, revalidate time-sensitive approvals, and compute the allowed next transition. Only then call the model. The model may help generate content or choose among policy-approved options, but it should not decide whether an ambiguous payment already happened.
8. Bound every loop
Carry retry counters and stop conditions across restarts. A crash must not reset the agent’s attempt budget. Connect this with explicit agent stop conditions: maximum iterations, elapsed time, cost, repeated tool errors, policy violations, and lack of progress.
Safe Resume: Why Checkpointing Must Be Paired With an Effect Ledger
The hardest recovery bug lives between “external action committed” and “checkpoint updated.” Suppose an agent submits an order, the order service creates it, and the worker crashes before saving the receipt. The latest checkpoint says the order is pending. Re-executing with a new request ID creates another order. Pretending that a database transaction covers both systems does not make it so.
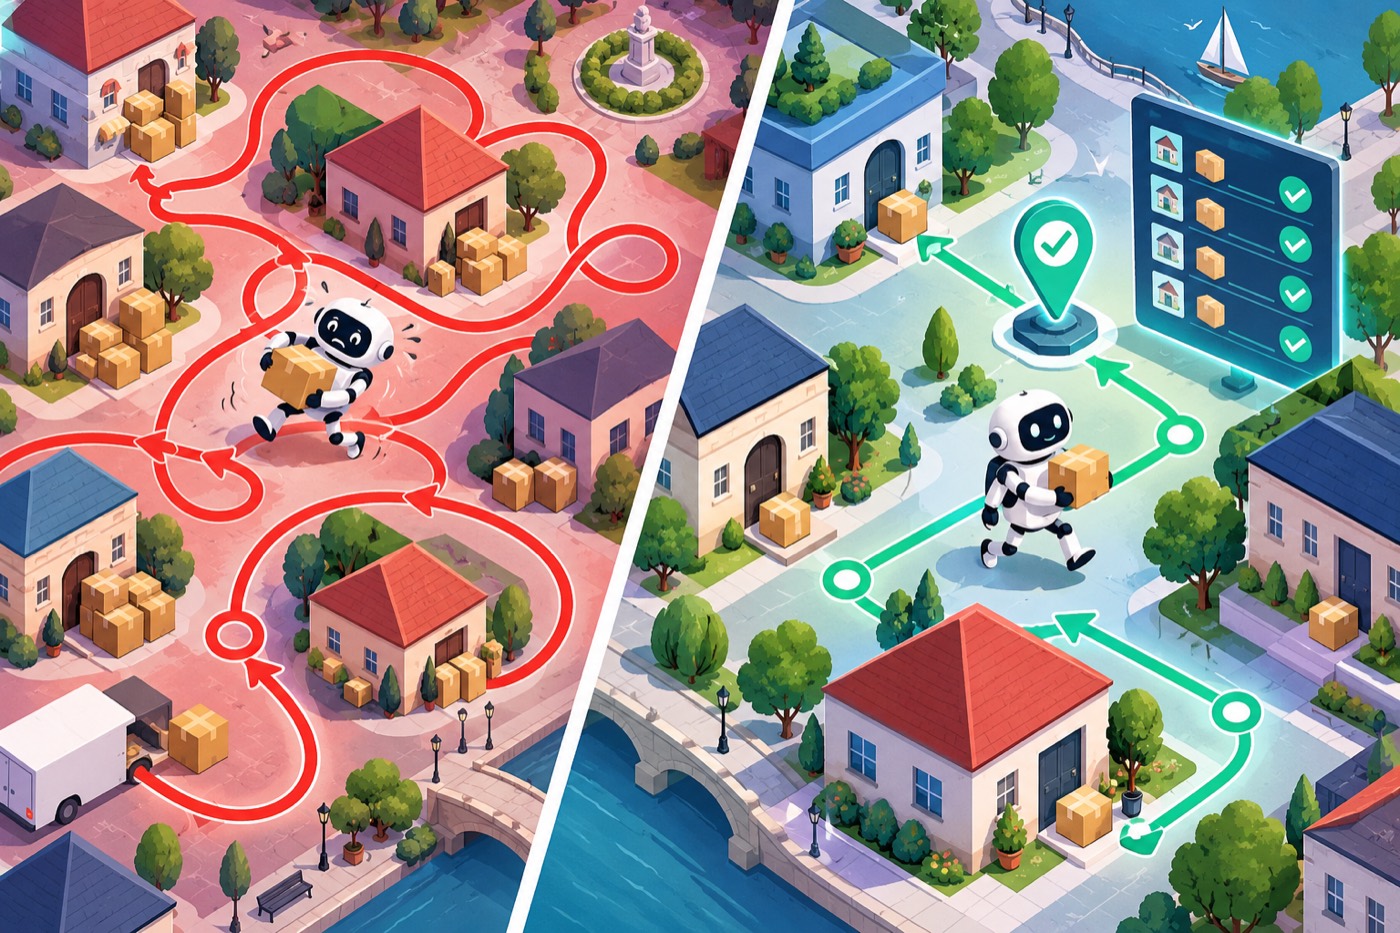
A checkpoint without effect reconciliation can faithfully return the workflow to the moment just before it repeats a real-world action.
This is why the recovery sequence begins with unresolved effects. For every operation marked started or unknown, query the target system. Use a stable business key, not a model-generated paraphrase. If the target lacks an idempotency or lookup contract, wrap it with an adapter you control or place a human gate before the action. High-impact tools should expose create-with-key, get-by-key, and status operations.
Safe recovery also needs compensation. If a later step fails after several confirmed effects, follow the workflow’s declared recovery policy. Some steps can be retried; some must be compensated; some cross a point of no return. The saga guide linked earlier covers that coordination. Checkpointing ensures the compensation worker can itself resume after a failure.
Finally, distinguish replay from re-execution. Durable engines may replay deterministic workflow code to rebuild local state, but they do not blindly repeat completed external activities. Your own framework should preserve that separation. Pure decisions may be replayed; side effects require receipts and idempotent activity contracts.
How to Test Checkpoint Recovery Before Production
A normal happy-path test proves almost nothing about checkpointing. Recovery tests must kill the workflow at awkward moments, change the environment, and verify both internal state and external effects. Add these scenarios to your AI agent test cases and run them whenever workflow, tool, prompt, or schema versions change.
| Fault injection | Expected recovery behavior | Assertion |
|---|---|---|
| Crash before external call | Resume from intent and execute once. | One downstream object; one committed receipt. |
| Crash after downstream commit but before response | Reconcile by stable key, then commit existing receipt. | No duplicate effect; state advances once. |
| Crash after checkpoint commit | Resume from the next state without rerunning the previous step. | Previous tool attempt count does not increase. |
| Two workers recover simultaneously | Only one acquires the valid lease or wins compare-and-swap. | Exactly one new checkpoint sequence. |
| Approval expires during downtime | Resume to a renewed approval gate, not the protected action. | No high-impact tool call under stale authority. |
| Checkpoint schema is old | Migrate through a tested adapter or quarantine the run. | No silent defaulting of missing security fields. |
| Artifact is missing or hash differs | Stop and regenerate or escalate according to policy. | Corrupted content is never published. |
| Model or prompt version changes | Compatibility policy chooses continue, branch, or restart. | Lineage records the decision and old state remains auditable. |
| Checkpoint record is tampered | Integrity verification rejects it. | No deserialization or tool execution from untrusted state. |
Test recovery at every boundary, not only once per workflow. A ten-step agent has more failure windows than “before” and “after.” Automate a kill switch that terminates the worker immediately before a call, after request transmission, after response receipt, after artifact upload, and just before checkpoint commit. Then restart against the same durable stores.
Measure recovery quality with operational metrics: resume success rate, duplicate side-effect rate, unresolved effect age, recovery time, checkpoints per successful run, storage growth, schema-migration failures, manual-intervention rate, and percentage of resumes that remain within budget. Pair those metrics with the failure categories in the AI agent failure taxonomy.
Security, Retention, Migration, and Production Operations
Treat checkpoints as sensitive state
A checkpoint may contain user data, internal source text, tool parameters, business records, approval identities, and artifact locations. Apply least-privilege access, encryption, tenant isolation, backups, deletion policy, and audit logging. Avoid putting personal information in identifiers. Validate every deserialized field before it influences a tool call.
Set retention by recovery need
Keeping every checkpoint forever increases storage cost and privacy exposure. Define separate windows for active recovery, incident investigation, compliance, and aggregate analytics. Compact older sequences into a final run record when detailed replay is no longer needed, while retaining effect receipts required for business reconciliation.
Version state as carefully as an API
Workflow code changes while runs are paused. Every checkpoint schema and state-machine definition needs a compatibility policy. For additive changes, a migration can supply defaults. For changed semantics or security rules, branch the run, require reapproval, or quarantine it. Never let a new model silently reinterpret an old action status.
Plan deployment around in-flight runs
Use a drain, migrate, or coexist strategy. A drain waits for old runs to finish. Migration transforms compatible checkpoints. Coexistence keeps old workers available for old schema versions. The right choice depends on workflow duration and risk. The AI agent deployment pipeline and agent change-management guide provide broader release context.
Design operator tools
Operators need more than a raw JSON viewer. Show the last committed state, unresolved effects, receipts, approval status, artifact hashes, current owner, compatible actions, and a reason for every blocked transition. Manual controls should be narrow: reconcile, retry with the same key, compensate, request approval, branch, or terminate. “Force complete” is usually too dangerous.
Define recovery objectives
Set an RPO for how much completed work may be lost and an RTO for how quickly a run should resume or escalate. Checkpoint placement directly influences both. A high-impact financial agent may need an intent record before every mutation and near-immediate reconciliation. A low-risk research agent may accept larger semantic intervals.
Typed schema, explicit version, lineage, committed step, next legal transitions.
Stable operation IDs, request hashes, idempotency keys, receipts, reconciliation.
Lease or compare-and-swap, duplicate-worker tests, queue redelivery handling.
Encryption, least privilege, integrity verification, tenant isolation, secret references.
Retention, compaction, backup, deletion, schema migration, deploy compatibility.
Recovery metrics, operator queue, dead-letter path, runbook, incident evidence.
Common Checkpointing Mistakes
Saving only the conversation
A transcript can help reconstruct context, but it does not prove state transitions or external effects. Convert important information into typed fields and verified receipts.
Generating a fresh idempotency key on resume
The key identifies the logical operation, not the network attempt. Reusing the original key is what allows the receiver to recognize a retry.
Marking a timeout as a failure
A timeout is an unknown outcome until reconciled. Treating it as a clean failure is how duplicate orders, messages, and charges happen.
Checkpointing unvalidated model output
Persistent nonsense is still nonsense. Validate schema, evidence, permissions, and business rules before advancing the state machine.
Ignoring version drift
Old state can become unsafe under new prompts, tools, or policies. Store versions and decide compatibility explicitly.
Letting restarts reset limits
Attempts, cost, time, and safety budgets belong to durable state. Otherwise, repeated crashes or redelivery can turn a bounded agent into an endless loop.
Assuming the queue is the database
A queue delivers work; it should not be the only proof of workflow progress. Redelivery is normal. Use durable state and concurrency control to decide whether the message is still actionable.
Testing only graceful shutdown
Real failures occur between instructions. Kill the process without cleanup and verify that the next worker can reconcile the last uncertain effect.
A Practical Adoption Plan
For an existing agent, begin with one workflow that is long-running or externally mutating. Draw its states and mark every side effect. Add stable workflow and operation IDs. Introduce an effect ledger before changing orchestration. Then add semantic checkpoints around expensive work, approval waits, and mutations.
Next, add recovery as a first-class command. It should load state, acquire ownership, reconcile uncertain effects, validate compatibility, and dispatch the next legal transition. Run it in staging with injected crashes. Only after duplicate-effect and stale-approval tests pass should automatic recovery be enabled.
Finally, connect the run to observability and incident response. A recovery failure should enter an operator queue with enough evidence to act. Use the AI agent incident response runbook when checkpoint corruption, duplicate effects, or unauthorized resumes cross your impact threshold.
FAQ About AI Agent Checkpointing
What is AI agent checkpointing?
AI agent checkpointing saves a versioned snapshot of committed workflow state so an interrupted run can resume from a safe boundary. A production checkpoint includes state-machine position, validated inputs, artifact pointers, approvals, budgets, tool intent, and references to confirmed external effects.
Is a conversation history the same as a checkpoint?
No. Conversation history is contextual data. A checkpoint is an execution contract. It must state which step is committed, what was validated, what external effects occurred, what remains unresolved, and which transitions are legal next.
How often should an AI agent create checkpoints?
Create checkpoints at semantic boundaries: before and after high-impact mutations, after expensive validated work, before human waits, at handoffs, and when ownership may change. Avoid saving every token unless a specialized runtime requires it.
Can checkpointing guarantee exactly-once tool execution?
No checkpoint alone can guarantee that. A crash can happen after the external system commits but before local state is updated. Use stable idempotency keys, an effect ledger, downstream lookup, and reconciliation to prevent duplicate side effects.
What is the difference between checkpointing and agent memory?
Checkpointing preserves execution state for one workflow lineage. Agent memory preserves reusable information such as preferences or facts across interactions. They can work together, but they have different authority and retention requirements.
Should checkpoints include model prompts and versions?
They should include prompt, model-contract, tool, and schema versions needed to judge compatibility. Avoid storing secrets or hidden chain-of-thought. Save explicit decisions, validated outputs, and concise operator-readable evidence instead.
How do I resume after an ambiguous tool timeout?
Load the original operation ID and idempotency key, query the downstream system, and verify the expected postcondition. Retry only when absence is confirmed, using the same logical key. Escalate when the target cannot prove the outcome and the effect is material.
How should checkpoint schemas be migrated?
Version every schema. Test explicit migrations for compatible changes. When semantics, authorization, or safety fields change, branch, reapprove, or quarantine the old run rather than silently supplying defaults.
What should I monitor in production?
Track resume success rate, duplicate-effect rate, unresolved effect age, recovery time, operator interventions, schema migration failures, checkpoint storage growth, and the percentage of recovered runs that stay inside their original budgets.

