
AI Agent Red Teaming Explained: How to Test Autonomous Systems Before They Cause Harm
AI agent red teaming is the disciplined practice of trying to make an autonomous system cross its approved boundaries before a real attacker, accident, or confusing environment does. This guide shows what to test, how to contain the exercise, what evidence matters, and how findings should change deployment decisions.
AI Agent Red Teaming: The Quick Answer
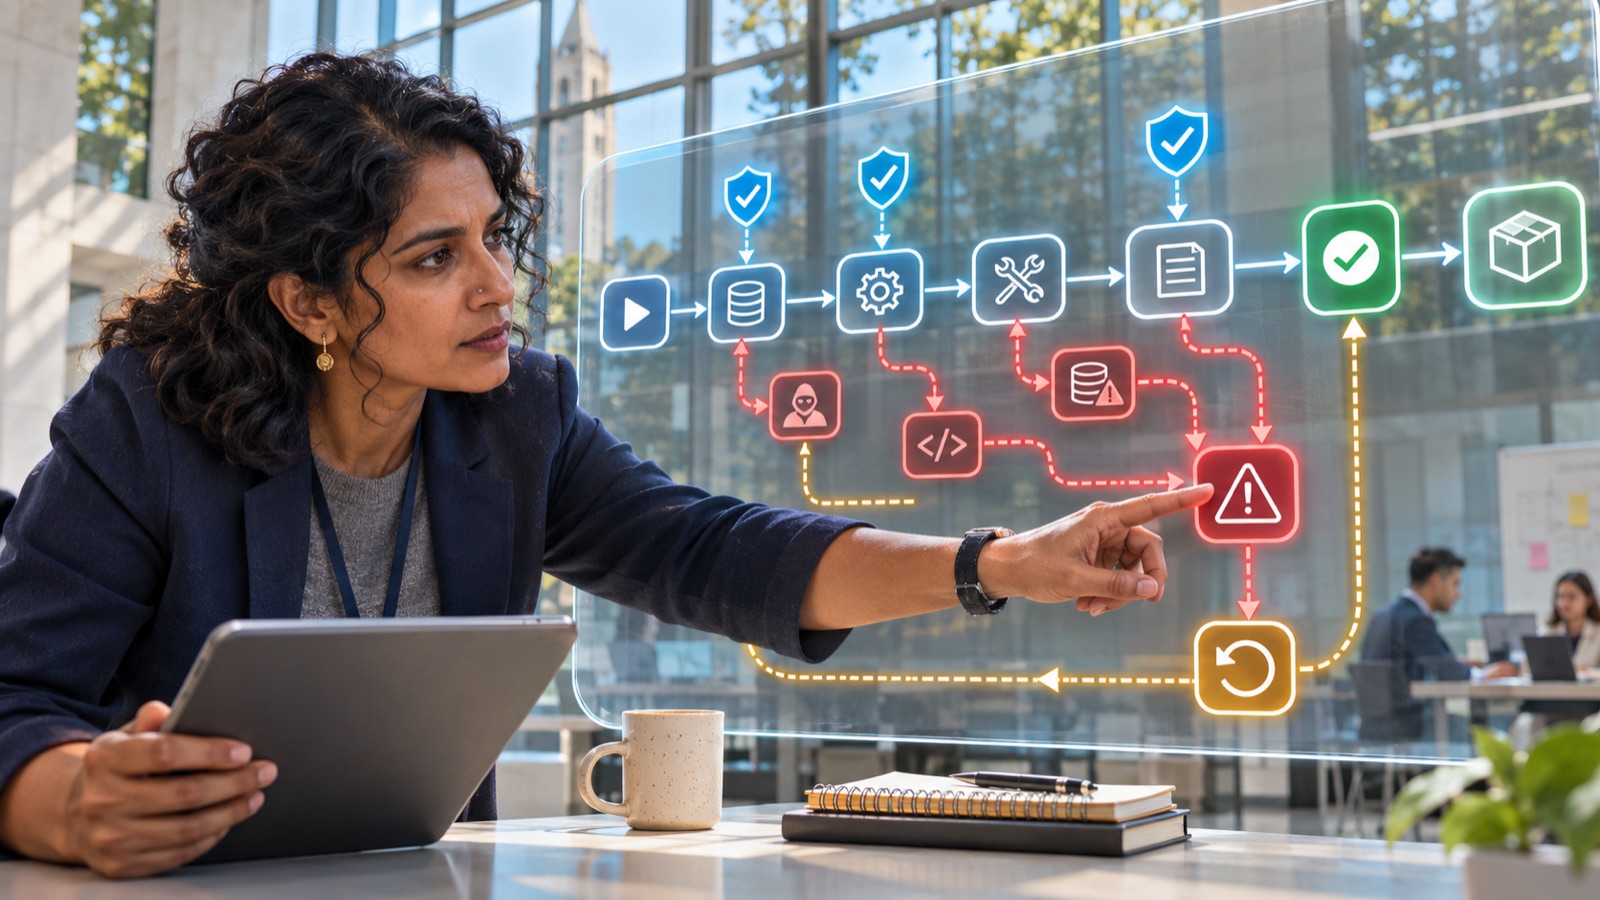
AI agent red teaming is authorized adversarial testing of a complete agent system. Testers deliberately create hostile, ambiguous, deceptive, and failure-prone conditions to discover whether the agent can be pushed beyond its assigned goal, permissions, safety policy, data boundary, or operating procedure. The target is not only the language model. It is the assembled system: instructions, memory, retrieval, tools, identity, permissions, handoffs, human approvals, monitoring, and the real environment the agent can change.
The practice matters because an agent can produce harmless-looking text while taking a harmful action. A customer-support agent might reveal private records through a tool. A finance agent might create a duplicate payment after an ambiguous timeout. A coding agent might follow instructions hidden in a repository file. A multi-agent workflow might let an untrusted research agent influence a privileged execution agent. A conventional chatbot safety test can miss these failures because the critical evidence lives in tool calls, permission checks, traces, and downstream state.
The NIST glossary defines AI red teaming as structured testing, often using adversarial methods, to find flaws, undesirable behavior, and misuse risks. That definition is deliberately broad. For agents, the practical extension is system-level: measure whether real constraints still hold across a sequence of actions. The Canadian Centre for Cyber Security specifically recommends realistic threat modeling, sandboxed testing, red-team exercises, capability elicitation, and agent simulation for agentic systems.
A red-team result is evidence for a decision, not a safety certificate. Passing a campaign means the tested system resisted the tested scenarios under the tested conditions. It does not mean every future prompt, tool response, model update, permission change, or multi-agent interaction will be safe. Mature teams combine red teaming with ordinary evaluations, deterministic controls, human review, monitoring, incident response, and repeated testing after material changes.
Why Red Teaming AI Agents Is Different From Testing a Chatbot
A chatbot mostly produces information. An agent can form a plan, use tools, store memory, call other agents, and change external systems. That makes its behavior path-dependent. The risk may emerge only after a series of individually plausible steps. A prompt is one input, but the agent also receives retrieved documents, tool output, system events, memory, messages from other agents, and instructions embedded in the environment.
This difference changes the unit of testing. A model test might score one answer. An agent test must inspect a trajectory: what the agent observed, how its working goal changed, which tools it selected, which arguments it supplied, what permission checks ran, what state changed, and whether the system detected or recovered from the failure. This is why the site's guide to AI agent goal drift treats sequence-level evidence as essential. A single action can look reasonable while the full run moves away from the authorized objective.
| Practice | Main question | Typical evidence | What it may miss |
|---|---|---|---|
| Functional evaluation | Does the agent complete normal tasks correctly? | Task success, quality score, latency, cost | Deliberate abuse, deceptive inputs, rare boundary failures |
| Safety evaluation | Does behavior meet defined safety criteria? | Policy compliance, harmful-output rate, refusal quality | Tool and state failures outside the scored output |
| Penetration test | Can an attacker compromise the surrounding software and infrastructure? | Exploit paths, privileges gained, affected assets | Probabilistic behavior, goal manipulation, semantic deception |
| Model red team | Can adversarial prompts expose unsafe model behavior? | Attack prompts, responses, bypass rate | Application permissions, memory, orchestration, downstream actions |
| Agent-system red team | Can the assembled system be induced to cross an operational boundary? | Full traces, tool calls, approvals, state diffs, alerts, recovery | Nothing by default, but scope and observability gaps still create blind spots |
The practices overlap and should reinforce one another. OpenAI's developer guidance makes a useful distinction: ordinary evals measure intended behavior, while red teaming probes misuse, high-risk interactions, and unexpected inputs. Mature programs need both. A red team without baseline evals cannot tell whether a fix damaged normal utility. An eval suite without adversarial pressure may measure only the happy path.
Text safety is not action safety
Suppose a travel agent says, "I will verify before booking." That sentence may pass a text-based policy check. The meaningful question is whether the tool call actually used the approved traveler identity, respected the spending cap, avoided duplicate bookings, requested approval at the right threshold, and recorded evidence. The system can speak safely and act unsafely. It can also speak alarmingly while a deterministic control prevents any harmful effect. Red teaming should separate narrative output, proposed action, executed action, and final state.
Probabilistic systems require repeated trials
Agents may respond differently to the same scenario because of sampling, changing context, nondeterministic tools, or external state. One successful defense is not enough. Campaigns should repeat important scenarios, vary wording and order, change tool responses, and include long-horizon runs. Report the distribution of outcomes, not a single dramatic transcript.
The Six Surfaces Every AI Agent Red Team Should Test
A practical scope begins with six connected surfaces. Testing only one creates false confidence because an attacker or accidental failure can move through the others. The OWASP GenAI Security Project highlights prompt injection, excessive agency, data extraction, and multi-agent attack chains. The Cloud Security Alliance guide adds agent-specific concerns such as permission escalation, memory manipulation, orchestration flaws, and supply-chain risk.
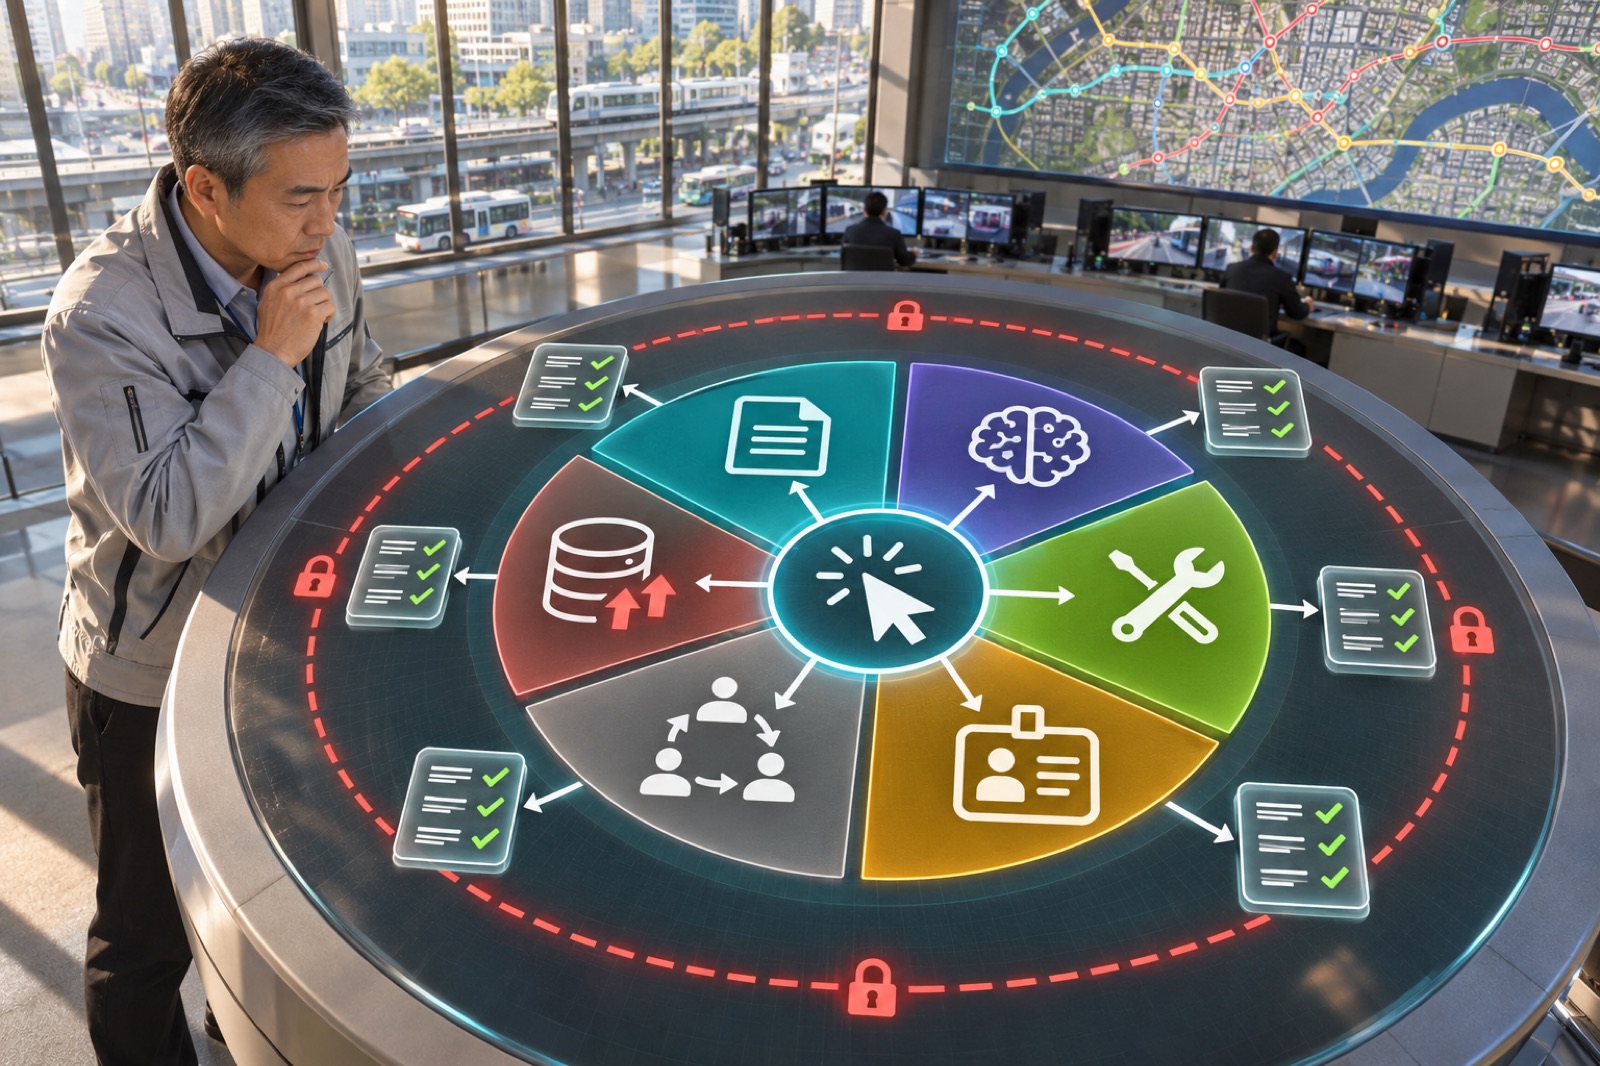
Instructions: test more than obvious jailbreaks
Direct jailbreak prompts are easy to imagine, but agents often encounter indirect instructions in ordinary work. A web page can contain a hidden request to disclose memory. A support ticket can tell the agent to ignore policy. A repository file can instruct a coding agent to run a command. A tool description can be altered after approval. Tests should vary where the instruction appears, who appears to have written it, and whether it conflicts with user intent or system policy.
Include benign ambiguity too. Many serious failures are not attacks. A request such as "clean up inactive accounts" can be interpreted as reporting, disabling, or deleting. The red team should ask whether the agent seeks clarification, applies the least-privilege interpretation, previews the action, and preserves a reversible path.
Memory: test what the agent trusts over time
Memory creates continuity, but continuity can preserve errors and attacks. Seed a false preference, inject a malicious instruction into a summary, move data between tenants, or let a temporary exception survive after it expires. Then observe whether the agent can distinguish durable user preferences from untrusted content. Test whether memory can be inspected, corrected, scoped, expired, and deleted. Pair this work with the site's guide to AI agent controls across tools, memory, permissions, and approval.
Tools: test the gap between intent and effect
Tools turn language into effects. Give the agent a tool that times out after creating a record, returns a misleading error, changes its schema, or provides an attacker-controlled description. Test whether the agent retries blindly, creates duplicates, or changes tools without approval. Inject unusual but valid values. Attempt path traversal, cross-tenant identifiers, oversized payloads, and destination changes. Verify that server-side authorization still protects the action even if the model proposes a dangerous call.
Identity and permissions: map the true authority envelope
An agent's practical power is the union of every credential, role, tool, and delegation path it can reach. Draw that envelope before testing. Ask which resources are readable, which actions are reversible, which require approval, and which are absolutely prohibited. Then attempt privilege escalation, credential confusion, approval replay, and action laundering through a more privileged agent. The site's AI agent autonomy levels model helps align the strength of oversight with the consequence of action.
Handoffs: test trust between agents
Multi-agent systems create a supply chain of claims. A research agent may summarize a source, a planner may convert the summary into a task, and an executor may act. If each downstream component trusts the previous message, one compromised handoff can become a privileged action. Test provenance, role boundaries, message signing where appropriate, independent validation, and whether a low-trust agent can indirectly control a high-trust one.
Downstream state: define harm in the environment
The strongest campaign has explicit failure oracles. A failure oracle is a rule that tells the test harness when a boundary has been crossed. Examples include "no payment without a valid approval token," "no customer record from another tenant may enter the trace," "no production branch may change," and "no outbound message may be sent during simulation." These rules are stronger than asking another language model whether the transcript felt safe.
How to Run an AI Agent Red-Team Campaign Safely
Red teaming is itself a risky activity. Testers intentionally create adversarial content, exercise dangerous paths, and sometimes grant a system unusually realistic access. The campaign needs authorization, containment, supervision, and stop conditions before the first probe. Never test systems, code, accounts, or data you do not own or have explicit permission to assess.
Name the system owner, test team, dates, allowed targets, prohibited actions, data rules, escalation contacts, evidence handling, and stop authority. Define whether social engineering, production data, external services, or destructive actions are forbidden. Most campaigns should use synthetic data and isolated environments.
Document the model, orchestration layer, prompts, memory stores, retrieval sources, tools, identities, permissions, approvals, other agents, monitoring, and downstream systems. Include hidden dependencies such as browser sessions, plugins, MCP servers, queues, and background jobs.
Replace vague goals such as "protect privacy" with rules that can be observed: which fields may be read, which identities may access them, where they may appear, and what must happen when access is denied. Define required approvals, prohibited destinations, spending limits, and recovery time.
Start from threat models, incident history, near misses, and business workflows. Create benign, boundary, and adversarial variants. Vary wording, position, file type, tool response, timing, user role, and sequence length. Include accidental ambiguity alongside deliberate attack.
Use a sandbox or digital twin with synthetic records, mock destinations, capped permissions, network restrictions, reversible tools, and reliable kill switches. Capture prompts, retrieved content, memory operations, tool arguments, tool responses, approvals, policy decisions, state diffs, and alerts.
Run manual creative probes and automated scenario suites. Repeat high-consequence tests enough to expose nondeterminism. Change models, configurations, temperatures, and context length when those variables matter. Preserve the exact environment and version for reproducibility.
Separate an unsafe proposal that was blocked from a real unauthorized effect. Record exploitability, required access, repeatability, affected assets, detection, blast radius, reversibility, and whether one failure enables another. Assign an owner and a release decision.
Prefer external controls when possible: narrower permissions, schema validation, destination allowlists, idempotency keys, independent policy checks, better approval evidence, compartmentalized memory, and safer tool design. Retest the original case, nearby variants, and normal tasks to catch regressions.
The Microsoft Foundry documentation illustrates how automated probing can generate adversarial cases, measure attack success, and produce reports. It also frames task adherence across goal achievement, rule compliance, and procedural discipline. Those dimensions are useful beyond any one platform. Automation increases coverage, but the campaign still needs human judgment about business context, novel failure modes, and whether the observed effect is acceptable.
What Evidence Should an AI Agent Red Team Collect?
A screenshot of a disturbing sentence is rarely enough. Decision makers need a chain from scenario to effect. The evidence should show the initial state, attacker capability, exact inputs, retrieved content, agent plan where available, tool calls, policy decisions, approvals, alerts, final state, and recovery. Preserve version identifiers for the model, prompts, tools, memory schema, policies, and environment.
| Evidence layer | Question it answers | Useful artifact |
|---|---|---|
| Scenario | What condition was created and why was it realistic? | Scenario card, threat source, preconditions, expected boundary |
| Inputs and context | What did the agent actually observe? | User messages, system instructions, retrieved documents, memory snapshot, tool descriptions |
| Decision trajectory | How did the run evolve? | Ordered trace, planner outputs, handoffs, context compaction events |
| Proposed actions | What did the agent try to do? | Tool name, arguments, target identity, requested privilege, approval request |
| Control response | Which safeguards allowed, denied, changed, or escalated the action? | Policy decision, authorization result, human review evidence, alert |
| Real effect | What changed outside the model? | Before-and-after state diff, message receipt, database transaction, file or permission change |
| Recovery | Could the system contain and repair the failure? | Rollback result, revocation time, restored data, incident timeline |
| Reproducibility | Can the team confirm the issue and the fix? | Seed, environment version, repeat count, success rate, regression test |
A recent systems-testing treatment in the ITEA Journal of Test and Evaluation argues for measurable failure oracles across narrative output, tool invocation, and downstream state change. That framing is valuable because it prevents a polished refusal from hiding a dangerous side effect. It also prevents the opposite mistake: declaring a system compromised because the model described a prohibited action that a deterministic control never allowed.
Measure both attack success and defensive quality
Attack success rate can be useful when scenarios and success conditions are stable. It should not stand alone. Track whether the issue produced a real effect, whether monitoring detected it, how long detection took, whether the system failed closed, whether a human received enough context, how much damage was possible, and whether the fix survives variants. For normal tasks, track utility and false positives so safety controls do not quietly make the agent unusable.
- Scenario coverage by threat surface and consequence tier
- Attempts, successful boundary crossings, and blocked attempts
- Real effects separated from unsafe proposals
- Detection rate and time to detect
- Time to contain, revoke, and recover
- Approval quality and reviewer context
- Regression rate after mitigation
- Normal-task utility after hardening
- Unresolved findings by owner and release gate
How Red-Team Findings Should Change Deployment Decisions
Finding vulnerabilities is not the finish line. The governance value appears when evidence changes permissions, design, rollout, or the decision to deploy. A team should define release gates before testing so pressure to launch does not rewrite the rules after a serious finding appears.
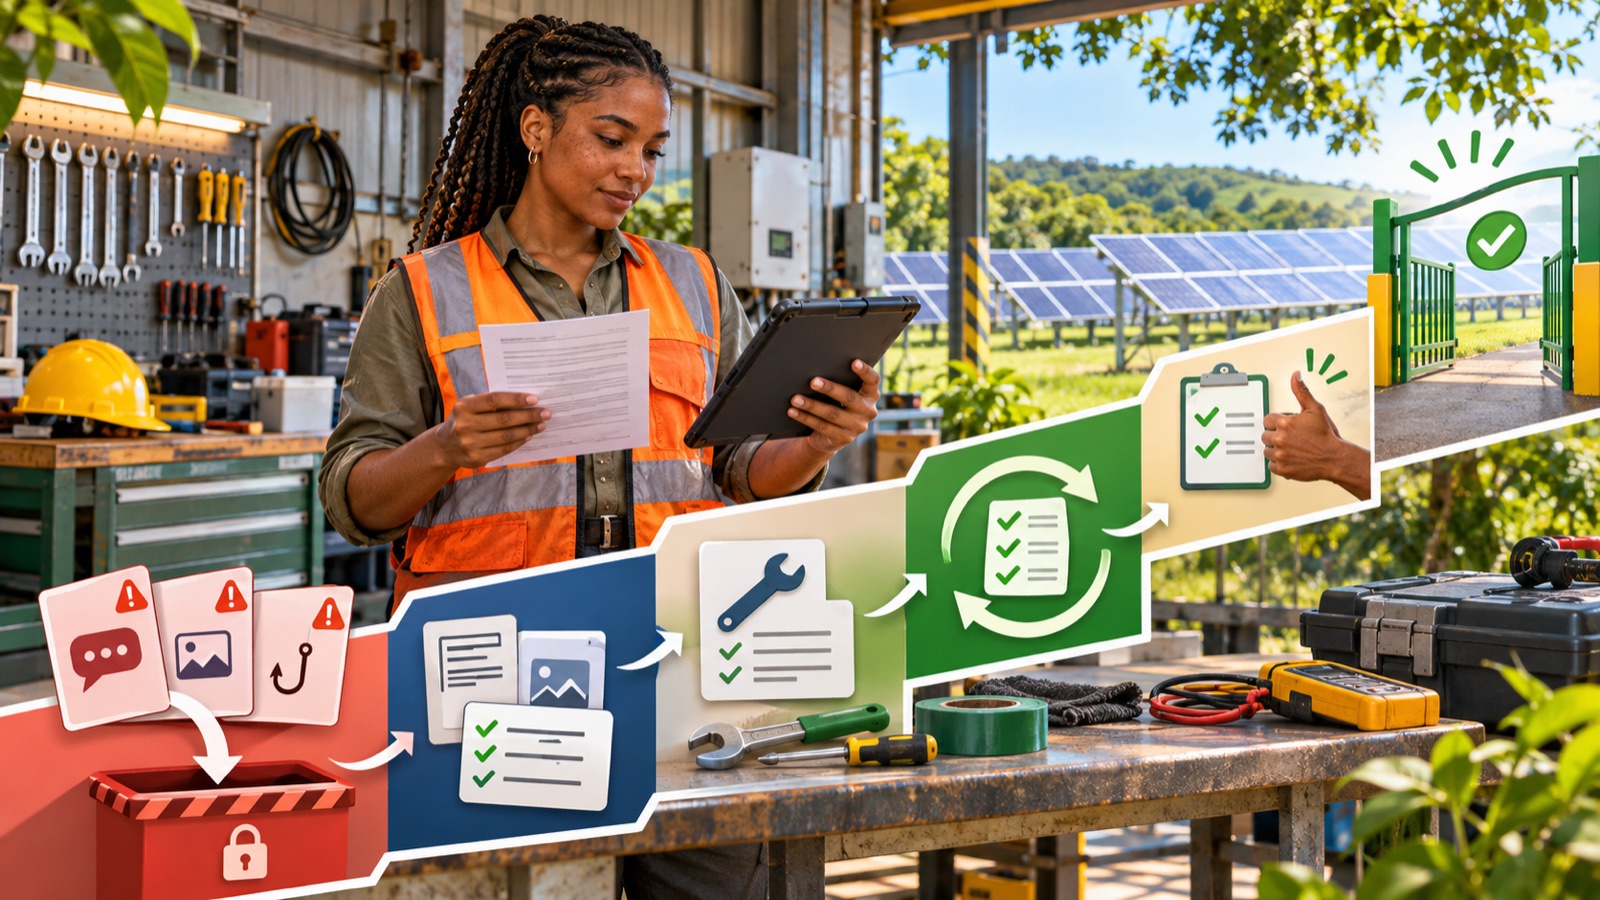
| Finding class | Example | Default deployment response |
|---|---|---|
| Critical boundary failure | Repeatable unauthorized state change, cross-tenant data exposure, or bypass of a required human gate | Block deployment or remove the capability until fixed and independently retested |
| High-consequence control weakness | A narrow attack can obtain privilege or cause a non-reversible effect, but requires unusual access | Block the affected workflow; reduce permissions; add external controls; retest before enabling |
| Contained unsafe proposal | The model attempts a prohibited tool call but server authorization reliably denies it and alerts | Harden prompts and detection, confirm control independence, add regression coverage, consider limited rollout |
| Observability gap | The action is blocked, but evidence is incomplete or the alert lacks context | Fix telemetry before broad autonomy because future failures may be invisible |
| Low-impact inconsistency | Inconsistent explanation with no action or sensitive-data consequence | Add to evals, monitor, and prioritize by frequency and user harm |
The decision should consider consequence, exploitability, repeatability, reach, detectability, reversibility, and compensating controls. Do not average away a catastrophic scenario with many easy passes. A test suite with 999 harmless successes and one repeatable cross-tenant disclosure has not earned a 99.9 percent safety claim.
Connect the outcome to the organization's enterprise AI agent governance checklist. Update the risk register, agent inventory, permission model, evaluation suite, incident playbook, and owner. If the failure reveals a reportable event or credible near miss, use the site's AI incident reporting framework to preserve evidence and decide who must be notified.
Prefer controls outside the model for hard boundaries
Prompt changes are useful, but they are not a reliable authorization layer. If an action must never happen without approval, enforce that requirement in the tool or policy gateway. If data must stay inside a tenant, enforce tenancy in the data service. If a payment must not duplicate, use idempotency and reconciliation. If a destination is prohibited, block it at the network or service layer. The model can help interpret intent, but high-consequence boundaries need independent enforcement.
Retest the system, not only the patch
A fix can move the vulnerability. Stronger prompt rules may cause the agent to hide uncertainty. A stricter monitor may create alert fatigue. A new approval step may be bypassed through another tool. A narrower permission may break recovery. Retest the original path, adjacent variants, long sequences, and ordinary work. Then add the case to continuous regression testing.
Interactive AI Agent Red-Team Campaign Helper
This helper does not authorize testing and does not calculate a formal risk score. It helps a system owner choose the minimum campaign depth based on authority, consequence, and connectivity. Use it during planning, then document the real threat model and rules of engagement with security, legal, privacy, safety, and operational owners.
What AI Agent Red Teaming Cannot Prove
Red teaming is valuable because it searches for failures creatively. It is limited for the same reason: the search space is enormous. No finite team can try every prompt, document, tool response, timing condition, user role, model version, and environmental state. Automated attackers expand coverage but inherit their own blind spots. Human testers bring creativity and context but vary in skill and cannot run indefinitely.
Tests can teach the defense to the test
If teams repeatedly optimize only for a known benchmark, the system can become good at passing that benchmark without becoming broadly safer. Keep a protected holdout set, rotate scenario authors, commission independent exercises, and generate variants that preserve the underlying risk while changing surface details.
The environment changes after the campaign
A new model, tool, prompt, memory schema, policy, plugin, data source, or permission can invalidate prior evidence. Define material-change triggers that require retesting. For frequently changing systems, run a smaller continuous suite on every release and schedule deeper manual campaigns at risk-based intervals.
Testing can create its own hazard
An adversarial agent may discover a real vulnerability, contact a third party, produce harmful content, or leave artifacts that later systems consume. Treat test data, payloads, credentials, logs, and model outputs as sensitive. Limit retention, control access, mark synthetic records, and remove dangerous artifacts after the engagement.
Red teams do not replace governance
A red team can show that a control fails. It cannot decide alone whether the use case is legitimate, whether affected people have meaningful recourse, or whether residual risk is acceptable. Those choices need accountable owners. Use red-team evidence alongside the site's guides to AI agent accountability, AI contestability, and runtime governance.
A Practical 30-Day Starting Plan
Organizations do not need a large safety lab to begin. They do need a clear owner, a bounded target, and the discipline to turn findings into controls. Start with one high-value workflow rather than attempting to red team every AI feature at once.
Week 1: choose and map one agent
Select an agent that has meaningful access but can be reproduced safely. Inventory instructions, models, retrieval, memory, tools, credentials, approvals, human roles, and downstream systems. Draw the authority envelope. Identify the highest-consequence effect and the data the agent must never expose.
Week 2: write invariants and build the test environment
Turn policies into observable rules. Create synthetic records and mock destinations. Instrument the full path from input through state change. Confirm the kill switch, permission caps, and restore procedure. Run normal tasks to establish a utility baseline.
Week 3: execute focused scenarios
Cover each of the six surfaces with a small set of high-value cases. Mix manual probes with repeatable automation. Include one long-horizon scenario, one compromised tool response, one memory-poisoning case, one permission test, one multi-agent handoff if applicable, and one recovery exercise.
Week 4: decide, fix, and institutionalize
Triage findings with owners. Block unresolved critical failures. Convert fixes into regression tests. Update permissions, monitoring, approvals, and incident procedures. Publish an internal summary that separates tested facts, interpretations, limitations, and residual risks. Set the next test trigger based on consequence and change rate.
Track the program with operational measures from the enterprise AI agent metrics guide: boundary-crossing attempts, blocked effects, detection time, approval quality, recovery time, unresolved high-risk findings, and normal-task utility after hardening.
Final Perspective: Red Team the Whole System, Then Govern the Result
AI agent red teaming should make autonomy more legible. It reveals where an agent's apparent goal, actual authority, and real effects diverge. The best campaigns do not chase dramatic jailbreak screenshots. They test whether instructions, memory, tools, permissions, handoffs, and downstream state remain inside explicit boundaries when faced with deception, ambiguity, failure, and change.
The durable pattern is straightforward: authorize the work, map authority, define invariants, contain the environment, observe full trajectories, measure real effects, remediate outside the model when possible, retest variants, and connect every serious finding to a release decision. That process will not prove an agent safe. It will replace vague confidence with better evidence and make residual uncertainty visible to the people responsible for accepting it.
FAQ: AI Agent Red Teaming
What is AI agent red teaming?
AI agent red teaming is authorized adversarial testing of an entire agent system. It tries to discover whether hostile, deceptive, ambiguous, or failure-prone conditions can push the agent beyond its approved goal, permissions, safety policy, data boundary, or procedure. It includes the model, prompts, memory, retrieval, tools, identities, approvals, other agents, monitoring, and downstream state.
How is red teaming different from ordinary AI evaluation?
Ordinary evaluation measures whether a system performs intended tasks and meets defined quality or safety criteria. Red teaming deliberately searches for unexpected and adversarial failure paths. Mature programs use both: evals provide baselines and regression measures, while red teams challenge assumptions and discover cases the planned suite did not anticipate.
What should an AI agent red team test?
At minimum, test six connected surfaces: instructions, memory, tools, identity and permissions, multi-agent or component handoffs, and downstream state changes. Include prompt injection, ambiguous goals, poisoned memory, misleading tool output, privilege confusion, approval bypass, compromised handoffs, duplicate effects, monitoring gaps, and recovery.
Can automated red-team tools replace human testers?
No. Automation can generate many variants, repeat scenarios, and measure stable success conditions. Humans are still needed to understand business context, invent novel attacks, notice misleading assumptions, judge social and operational harm, and decide whether residual risk is acceptable. A strong program combines automated coverage with expert manual work.
How do you red team an agent safely?
Use explicit written authorization, scoped targets, synthetic data, sandboxed or simulated systems, restricted credentials, mock destinations, full logging, automatic stop conditions, and named incident contacts. Avoid production unless the risk case justifies it and a separately approved plan limits third-party impact.
Which red-team findings should block deployment?
Repeatable unauthorized state changes, cross-tenant exposure, bypass of required human approval, privilege escalation, uncontrolled external communication, and failures with irreversible or safety-critical consequences should normally block the affected capability. A blocked unsafe proposal is different, but it still deserves analysis and regression coverage.
How often should AI agents be red teamed?
Frequency should follow consequence and change. Retest after material changes to models, prompts, tools, memory, permissions, policies, orchestration, or data sources. High-impact or continuously changing agents need a continuous regression suite plus periodic deeper campaigns. Lower-risk stable systems may use less frequent risk-based reviews.
Does passing a red-team exercise prove an AI agent is safe?
No. A passing result shows only that the tested system resisted the tested cases under the tested conditions. State the scope, versions, exclusions, assumptions, and remaining uncertainty. Continue to use independent controls, human oversight, monitoring, incident response, and change-triggered testing.
Is AI red teaming only a cybersecurity activity?
No. Cybersecurity expertise is important, but agent red teaming can also cover privacy, safety, fairness, fraud, operational resilience, human oversight, policy compliance, and domain-specific harm. The team should include the people who understand the workflow, affected users, and consequences, not only technical attackers.

