
AI Agent Operations Engineer Roadmap: Skills, Projects, and a Path Into AgentOps
An AI Agent Operations Engineer keeps production agents observable, evaluated, controlled, recoverable, and worth the cost. This guide maps the role, transferable skills, portfolio evidence, and a practical learning path for people coming from SRE, DevOps, QA, data, support, security, governance, or business operations.
AgentOps combines production reliability, behavioral evaluation, human oversight, and continuous improvement.
AI Agent Operations Engineer: The Quick Answer
An AI Agent Operations Engineer owns the dependable day-to-day operation of AI agents after they leave a prototype. The work includes telemetry, evaluations, release gates, incident response, human escalation, permission checks, cost controls, knowledge quality, and learning from failures. The role is not simply prompt writing, dashboard watching, or traditional infrastructure support. It connects technical system health with whether the agent actually completed the right task safely.
The title is still emerging, so employers may call similar work AgentOps Engineer, AI Agent Ops Lead, AI Reliability Engineer, LLMOps Engineer, AI Production Engineer, Agent Evaluation and Instrumentation Lead, or AI Operations Specialist. Do not build a career plan around one exact label. Build evidence around the recurring responsibilities.
Recent employer listings make those responsibilities unusually clear. A Singtel role for AI and agent operations describes ownership of monitoring, evaluations, observability, incident response, service-level objectives, error budgets, model performance, cost, governance, and go or no-go authority. A Just Eat Takeaway.com listing adds knowledge management, business readiness, analytics, testing, and continuous improvement. Other listings emphasize workflow design, human-agent handoffs, tool failures, and operational governance. These postings are examples, not a complete labor-market census, but they show that the work is becoming specific enough to hire for.
The best candidates usually have a strong base in one adjacent discipline and enough breadth to connect the rest. An SRE might bring incident judgment and observability. A QA engineer might bring test design and reproducibility. A data or ML engineer might bring pipelines and drift analysis. A support operations leader might bring escalation design, domain knowledge, and outcome measurement. The goal is not to become expert in everything. It is to become the person who can answer, with evidence: Is this agent healthy, is it useful, is it allowed to do this, and what should happen next?
What an AI Agent Operations Engineer Actually Does
Agent operations begins where a demo stops being impressive and starts becoming accountable. A prototype can succeed once in front of its creator. A production agent must work across many users, inputs, tools, permissions, model versions, and changing business conditions. It also needs a safe response when it cannot complete the task.
The job can be understood as six repeating loops: instrument, evaluate, detect, respond, govern, and improve. Instrumentation records what the agent attempted, which tools it called, what context it used, how long each step took, and what the result cost. Evaluation tests whether the final outcome and intermediate behavior met quality criteria. Detection turns telemetry and evaluation signals into useful alerts. Response contains harm, restores service, and communicates clearly. Governance defines authority, approvals, evidence retention, and escalation. Improvement converts incidents, user feedback, and failed evaluations into safer releases.
Before release
Define task-success criteria, build representative evaluation sets, inspect tool permissions, confirm fallback paths, set release gates, and decide which failures must stop deployment.
During operation
Monitor latency, errors, task completion, tool behavior, policy violations, escalation quality, cost, and user impact without treating every unusual trace as an emergency.
During an incident
Determine scope, pause risky capabilities, route work to a safe fallback, preserve evidence, coordinate owners, communicate impact, and choose recovery criteria.
After an incident
Reconstruct the agent journey, separate trigger from contributing conditions, update evaluations and controls, verify remediation, and measure whether recurrence actually falls.
Traditional monitoring asks whether the API responded. Agent operations also asks whether the response was appropriate. An agent can return HTTP 200, stay within latency targets, and still select the wrong tool, retrieve stale policy, loop through expensive actions, expose data, or confidently complete the wrong business task. This is why AgentOps joins infrastructure signals with behavioral and outcome signals.
OpenTelemetry's work on GenAI semantic conventions is useful here because standardized names for agent, model, operation, and conversation attributes make traces easier to compare across services. The standard is evolving, so a good operator understands both the benefit of common telemetry and the danger of collecting sensitive prompts or tool outputs without a clear need. Observability is not maximal recording. It is enough structured evidence to diagnose, evaluate, and improve the system responsibly.
AgentOps vs MLOps, SRE, Evaluation, and Governance
The fastest way to misunderstand this career is to treat it as a renamed version of one existing job. It borrows from several disciplines, but its center of gravity is different. AgentOps owns the operating outcome of a system that can reason across steps, call tools, modify state, and ask humans for judgment.
| Discipline | Primary question | Typical ownership | AgentOps connection |
|---|---|---|---|
| SRE or DevOps | Is the service reliable and operable? | Availability, latency, deployment, capacity, incidents, SLOs | Adds agent behavior, task outcomes, tool paths, and safe fallback to production reliability. |
| MLOps | Can models and data pipelines be deployed and maintained? | Training, registry, data quality, drift, deployment, model lifecycle | Adds multi-step orchestration, prompt and tool changes, delegated action, and business-process outcomes. |
| AI evaluation engineering | How well does the system behave under defined tests? | Datasets, graders, rubrics, experiments, regression analysis | Turns evaluation into release gates, production sampling, alerts, and remediation decisions. |
| AI governance | Are risks, responsibilities, controls, and evidence adequate? | Policy, risk classification, accountability, audit, oversight | Implements those controls in daily operations and provides operational evidence back to governance. |
| Business operations | Does the workflow create the intended customer or company outcome? | Process, service quality, staffing, exceptions, KPIs | Connects agent traces and technical controls to real workflow completion and customer impact. |
In a small company, one person may cover most of these areas. In a large enterprise, AgentOps may be a team that partners with platform engineering, security, product, legal, support, domain owners, and an evaluation function. The boundaries should be explicit. If everyone can stop an agent but nobody is clearly accountable for deciding when it may resume, an incident will expose the gap.
NIST's AI Risk Management Framework supports this division of work. Its core calls for defined human roles, production monitoring, documented response and recovery, incident communication, and continual improvement. Those outcomes do not prescribe a job title, but they describe operational responsibilities that someone must own. That makes the career durable even if the label changes.
The Six-Layer AgentOps Skill Stack
A credible roadmap needs more than a list of tools. Tools change quickly. Build skills in layers, and connect each layer to a visible artifact that proves you can use it.
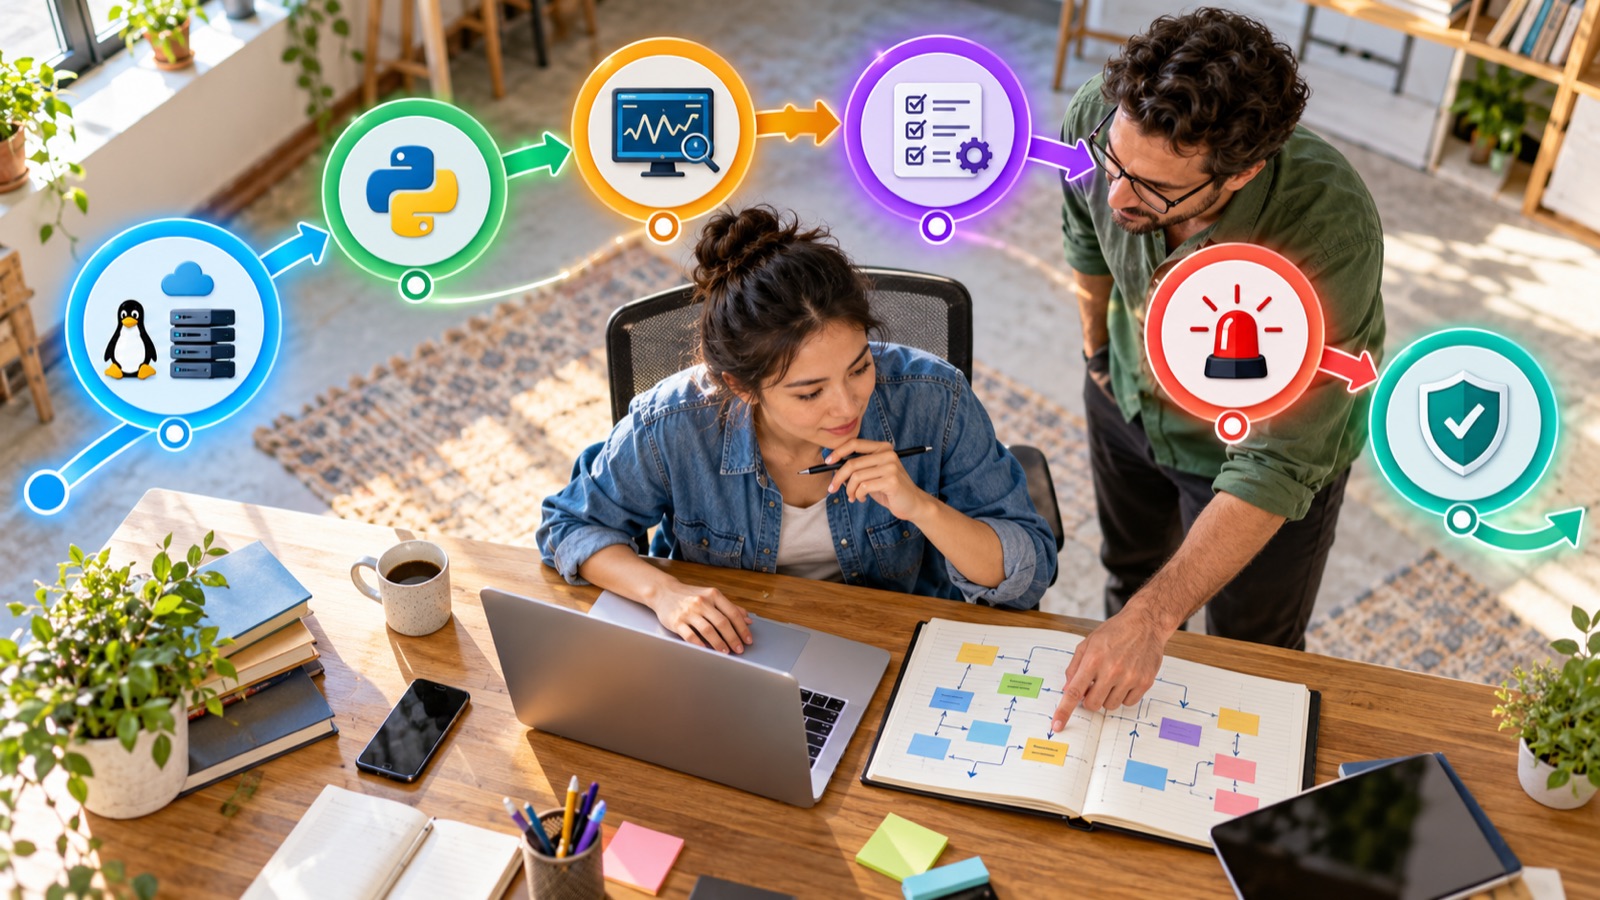
The strongest roadmap starts with an adjacent foundation and adds agent-specific operations skills.
1. Systems and automation foundations
Learn enough Linux, networking, APIs, authentication, databases, queues, cloud services, containers, and version control to follow a request across boundaries. Python is especially useful for log analysis, evaluation harnesses, data sampling, and automation, but the point is not language prestige. The point is being able to inspect evidence and change a repeatable process.
2. Agent architecture literacy
Understand the difference between a fixed workflow and a model-directed agent. Be able to draw an agent loop with input, context, model call, tool selection, action, observation, state, stopping condition, and human checkpoint. Learn how retrieval, memory, tool schemas, permissions, and orchestration affect behavior. Anthropic's guidance on effective agents is helpful because it stresses simple composable patterns, ground truth from the environment, checkpoints, and stopping conditions rather than complexity for its own sake.
3. Observability and journey reconstruction
Learn logs, metrics, traces, correlation identifiers, sampling, dashboards, and alert design. Then extend them to agent-specific questions: Which version ran? Which prompt and policy applied? Which tools were considered and called? What state changed? Where did latency and cost accumulate? Did the agent escalate? Could another operator reconstruct the journey without reading private data that should never have been captured?
4. Evaluation and quality engineering
Build task-level test cases with clear rubrics, reference outcomes where appropriate, and representative edge cases. Learn deterministic checks, model-based graders, human review, inter-rater disagreement, false-positive analysis, and regression testing. Agent evaluations must often inspect both the final result and the path taken. A refund agent that reaches the right answer by querying an unauthorized system still failed.
5. Reliability and incident response
Learn SLOs, error budgets, on-call basics, severity, triage, containment, rollback, graceful degradation, postmortems, and change management. Google SRE guidance treats an error budget as the allowed distance from an SLO and a mechanism for balancing release speed with reliability. AgentOps adapts that idea carefully: teams may need budgets for failed task outcomes, unsafe tool attempts, excessive escalations, or unrecoverable journeys, not only downtime.
6. Governance, security, and human factors
Understand least privilege, data handling, audit evidence, authorization, approval design, separation of duties, contestability, and the limits of automation. The World Economic Forum's agent playbook emphasizes authorization profiles and operational oversight. In practice, an AgentOps engineer turns those principles into deployable controls, review queues, escalation paths, and evidence that a decision was followed.
Which Backgrounds Transfer Best Into AgentOps?
There is no single entry route. The best route is usually adjacent, not from zero. Start with the strengths you already have, then close the risks your background tends to overlook.
| Feeder background | What transfers | Likely gap | Best first proof |
|---|---|---|---|
| SRE, DevOps, cloud operations | Telemetry, incidents, automation, deployment, SLO thinking | Behavioral evaluation, domain quality, human review | Add task-success evals and a safe fallback to an observable agent service. |
| QA or test engineering | Test design, edge cases, regression discipline, reproducibility | Cloud operations, tracing, production response | Build an agent eval suite tied to release gates and production samples. |
| Data or ML engineering | Pipelines, experiments, data quality, model lifecycle | Delegated action, tool security, incident command | Instrument a tool-using agent and run a controlled failure exercise. |
| Security operations | Threat detection, access control, investigations, response | Task quality, model behavior, business workflow design | Create an agent permission map plus trace-based misuse detection. |
| Customer support or business operations | Exception handling, domain judgment, escalations, service outcomes | Code, APIs, telemetry, deployment mechanics | Model a real workflow, define success and escalation, then prototype a measurable agent. |
| AI governance or risk | Controls, documentation, accountability, audit, policy | Hands-on instrumentation and operational debugging | Translate a policy into a working approval gate, evidence log, and incident runbook. |
A non-coder can contribute meaningfully, especially in domain operations, evaluation design, knowledge quality, and oversight. However, the engineer title usually implies hands-on technical depth. If that is your target, learn enough scripting, APIs, version control, and telemetry to build and debug a small system independently. You do not need to train a foundation model. You do need to understand how a production agent interacts with the systems around it.
LinkedIn's broader labor-market reporting shows strong growth in AI roles and demand for AI literacy beyond engineering. That supports the value of combining AI capability with existing domain expertise, but it does not prove a specific number of AgentOps openings. Use the signal correctly: the market rewards AI skills, while exact titles and team structures remain fluid.
Four Portfolio Projects That Prove AgentOps Readiness
A useful portfolio should make operational judgment visible. A chatbot screenshot proves very little. Show how the system behaves, how you know, what happens when it fails, and how you improved it.
Project 1: An observable tool-using agent
Build a narrow agent that reads a small knowledge base and calls one safe tool, such as creating a ticket in a sandbox. Instrument each run with a correlation identifier, model and agent version, tool latency, token or cost estimate, completion state, and escalation reason. Create a dashboard that separates infrastructure errors from task failures. Include a short privacy note explaining what you deliberately did not log.
Project 2: A release evaluation gate
Create 50 to 100 test cases representing normal tasks, edge cases, adversarial instructions, stale knowledge, missing permissions, and ambiguous requests. Use deterministic checks where possible and a clear rubric for judgment calls. Compare two versions, inspect disagreements, and define a release rule. Report not just a single score, but failure categories and confidence limits. Explain how the test set could become stale.
Project 3: An incident simulation and recovery runbook
Inject failures such as a slow tool, malformed response, stale retrieval source, provider outage, recursive loop, or unauthorized action. Show detection, severity, containment, safe fallback, evidence preservation, communication, recovery criteria, and a post-incident improvement. A good demonstration includes a case where the agent stays technically available but produces a harmful business outcome.
Project 4: An authorization and human-oversight design
Define a small agent estate with roles, tools, data, and risk tiers. Specify which actions are automatic, which require approval, which are prohibited, and who can change the policy. Implement at least one approval gate and one kill switch. Record decisions in an audit-friendly format. Then run usability tests: a control that operators bypass under pressure is not a mature control.
| Artifact | What a reviewer should see | Evidence of maturity |
|---|---|---|
| Architecture diagram | Agent, tools, state, data, people, boundaries | Trust boundaries and failure paths are explicit. |
| Telemetry dictionary | Events, attributes, metrics, retention | Sensitive fields and sampling choices are justified. |
| Evaluation report | Dataset, rubric, scores, failure categories | Uncertainty and grader limitations are discussed. |
| Runbook | Detection, triage, containment, recovery | Ownership and decision authority are clear. |
| Postmortem | Impact, timeline, conditions, actions | Actions are testable and linked to recurrence risk. |
| One-page decision memo | Ship, hold, restrict, or retire recommendation | Business value and risk are connected to evidence. |
Host code and sanitized sample data where appropriate, but do not publish secrets, copied employer data, proprietary prompts, or real customer traces. Synthetic evidence is acceptable when labeled clearly. Honesty about constraints is a stronger signal than a polished but unverifiable claim.
A Practical 90-Day Learning Roadmap
Ninety days will not make someone senior, but it can produce enough evidence to test fit, improve interviews, and earn a stretch assignment. Adjust the pace around your existing strengths.
Days 1 to 30: Build the operating model
- Draw the lifecycle of one tool-using agent from request through action and review.
- Review APIs, authentication, Python, containers, and Git at the depth your feeder background needs.
- Learn logs, metrics, traces, correlation, sampling, and basic alert design.
- Read official guidance from NIST, OpenTelemetry, Anthropic, Google SRE, and the World Economic Forum.
- Define task success, unsafe outcomes, and escalation rules for one narrow use case.
At the end of month one, you should be able to explain why service uptime and agent success are different. You should also be able to identify who owns the business outcome, the data, the tool, the agent configuration, and the incident decision.
Days 31 to 60: Build and break the system
- Create the observable agent and a small evaluation set.
- Version prompts, tools, model choice, policy, and evaluation data.
- Inject at least five failures and record whether detection worked.
- Add a human checkpoint for a consequential action.
- Create one dashboard for system health and another for task outcomes.
Do not optimize for a perfect demo. Optimize for explainability. Keep a lab notebook showing what failed, what you changed, and how the evidence moved. That notebook often reveals more skill than the final interface.
Days 61 to 90: Operate, communicate, and package proof
- Run a release comparison and write a ship or hold memo.
- Conduct an incident exercise with a friend acting as product or business owner.
- Write a blameless postmortem and convert findings into new tests.
- Publish a sanitized architecture, runbook, evaluation summary, and two-minute walkthrough.
- Map five target job descriptions to your evidence and close the most repeated gap.
Your portfolio story should follow a simple pattern: context, risk, ownership, signal, decision, action, and verified result. Avoid vague claims such as “improved reliability.” Say what you measured, what changed, what remained uncertain, and what you would do with real traffic.
The Metrics an AgentOps Engineer Should Understand
Metrics are decision tools, not decoration. A strong operator knows which question each metric answers and which behavior it might accidentally encourage.
| Metric family | Examples | Decision it supports |
|---|---|---|
| Reliability | Availability, latency, timeout rate, tool error rate, recovery time | Is the system technically able to serve work? |
| Outcome quality | Task completion, correctness, journey completion, user correction | Did the agent accomplish the intended work? |
| Behavior | Tool selection, retry or loop rate, policy violations, unsupported claims | Did it follow an acceptable path? |
| Human oversight | Escalation rate, review latency, override rate, approval quality | Are humans involved at the right moments and able to act? |
| Safety and security | Blocked actions, permission denials, sensitive-data events, anomalous access | Are controls preventing or containing unacceptable action? |
| Cost and efficiency | Cost per verified outcome, tokens per task, tool calls, rework, abandonment | Is the workflow economically useful, not merely active? |
| Learning | Recurrence rate, eval coverage, detection coverage, remediation age | Is the operating system improving over time? |
Do not chase the lowest escalation rate. A falling rate might mean the agent improved, or it might mean users stopped reporting failures. Do not chase the highest automated completion rate if difficult cases are being forced through without review. Do not use average latency alone when a small tail of stuck journeys causes the real harm.
Anthropic's published discussion of monitoring its internal agents offers a useful example of measures such as monitoring coverage, review latency, and escalation rate. Those numbers describe one environment and should not be copied as universal targets. The lesson is the reporting structure: state what is covered, how quickly review occurs, what gets blocked or escalated, and what limitations remain.
How AgentOps Handles an Incident
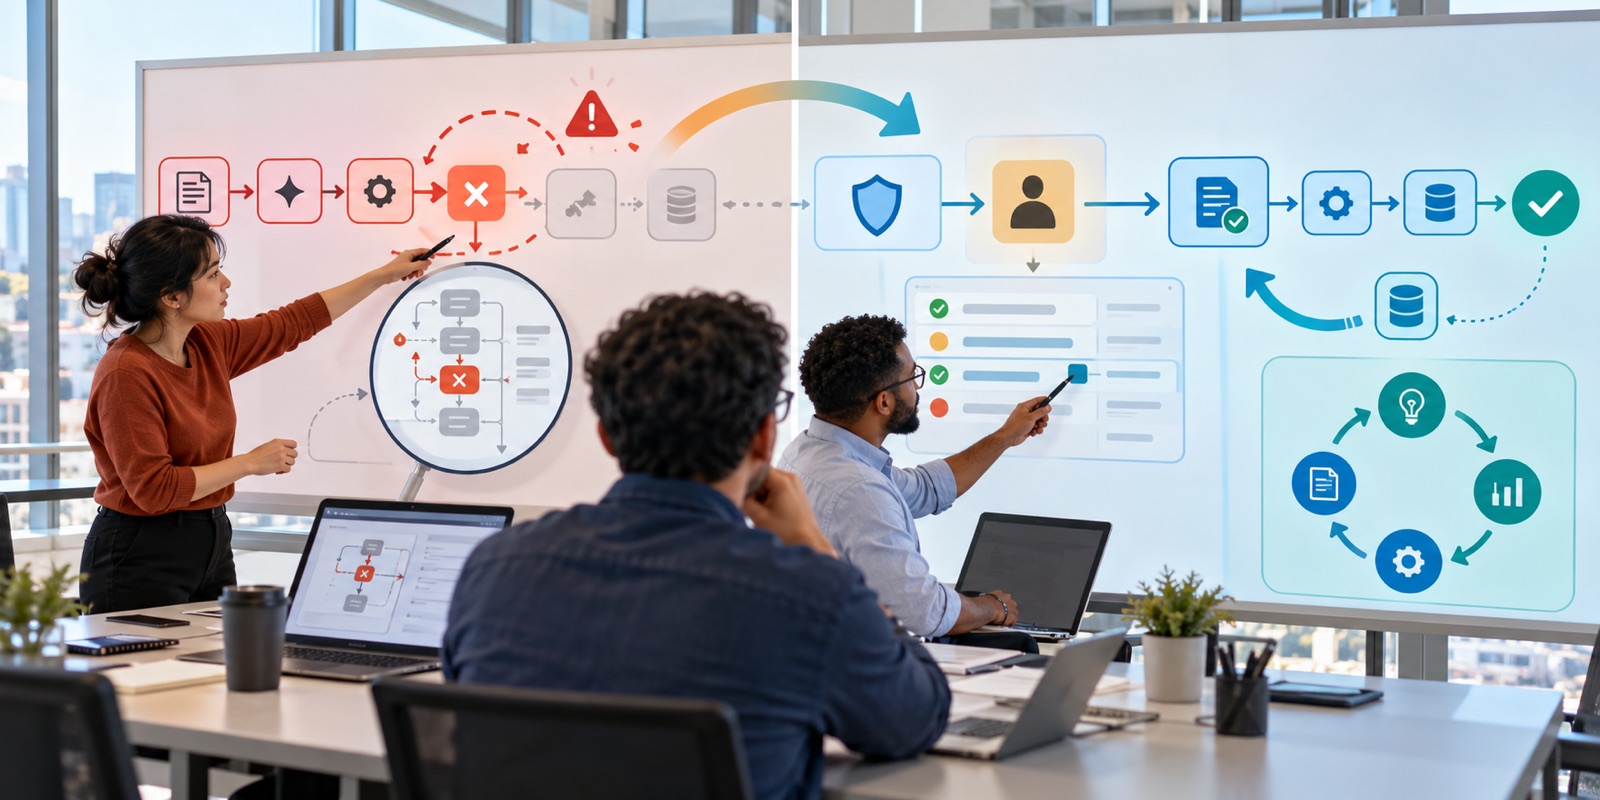
A mature response moves from detection to containment, human judgment, recovery, and learning.
Imagine a customer-support agent that can issue account credits. Infrastructure dashboards are green, but the agent begins granting credits outside policy after a knowledge update changed how it interprets eligibility. This is an AgentOps incident because the service is available while the business behavior is wrong.
First, confirm the signal and scope. Which agent version, policy version, customer segment, and tool path are affected? Second, contain the risky capability. Disable the credit tool or require approval while preserving safe read-only assistance. Third, protect customers and evidence. Stop further harmful action, retain relevant traces under the approved policy, and notify owners. Fourth, recover to a known-good configuration or corrected policy. Fifth, verify with targeted evaluations and monitored traffic before restoring authority.
The postmortem should not stop at “the prompt was wrong.” Ask why the change passed review, why monitoring detected it late, why authorization allowed the amount, and why the fallback was or was not effective. Useful remediations could include a deterministic credit limit, a policy-version check, test cases drawn from the incident, a canary release, an alert on unusual credit distribution, and clearer ownership for knowledge changes.
This scenario demonstrates the career's hybrid nature. Debugging requires traces and version control. Evaluation requires domain examples and rubrics. Containment requires permissions and a kill path. Communication requires operational clarity. Recovery requires testing and risk judgment. Improvement requires changing both the system and the process around it.
How to Prove AgentOps Skill in Interviews
Interviewers for an emerging role may not use a standard question bank. Prepare to reason across incidents, system design, metrics, and organizational boundaries.
Tell evidence stories, not tool inventories
A weak answer says, “I used LangGraph, Grafana, and OpenTelemetry.” A strong answer says, “We could see API latency but not which tool path caused failed outcomes, so I added trace correlation across the agent and ticket system, created a task-success sample, and separated provider errors from policy failures. That changed the on-call decision from restarting the service to restricting one tool.”
Expect scenario questions
- An agent's latency and availability are healthy, but user complaints rise. How do you investigate?
- A new model improves average quality but doubles cost and worsens a critical edge case. Do you release?
- Human reviewers approve nearly everything. Is that success or oversight theater?
- A tool call times out after the external system may have completed the action. How do you recover safely?
- What would you log, and what would you refuse to log?
- Who may stop the agent, who may resume it, and what evidence is required?
Use a consistent structure: define impact, identify missing evidence, establish safe containment, investigate across versions and boundaries, propose recovery criteria, and add a prevention or detection improvement. Say when you need domain, security, legal, or product judgment. Mature operations is collaborative, not heroic.
Ask the employer diagnostic questions
Ask how many agents are in production, which actions they can take, who owns business outcomes, how evaluations influence releases, how on-call works, what data operators may access, and whether the team has authority to restrict or roll back a capability. These questions reveal whether the role is genuine AgentOps, general support with a new label, or a build role disguised as operations.
Also ask what success looks like after six months. Reasonable answers might include better journey reconstruction, fewer recurring failures, improved evaluation coverage, faster safe containment, clearer ownership, or lower cost per verified outcome. Be cautious if success is only “more agents deployed.”
Common Career Mistakes to Avoid
Learning only prompts
Prompts matter, but production failures also involve tools, data, permissions, state, models, networks, people, and incentives.
Copying universal thresholds
A good escalation rate or latency target depends on consequence, workflow, users, and fallback. Explain how you would set it.
Building only happy-path demos
Employers need people who can detect and recover from failure. Deliberately break your portfolio system.
Confusing dashboards with observability
A dashboard is useful only if an operator can connect a signal to a journey, decision, owner, and response.
Ignoring domain expertise
An operator cannot judge task success without understanding what correct work means in that business context.
Overstating a new title
Use exact evidence from listings, but admit that titles and boundaries vary. Sell transferable responsibility, not hype.
The role will evolve. Some organizations will absorb it into SRE or MLOps. Others will create dedicated agent operations and evaluation teams. Some business units will use operations leads who are less technical but deeply knowledgeable about the workflow. Your durable advantage is not attachment to a label. It is the ability to operate probabilistic, tool-using systems with evidence, judgment, and clear human authority.
Sources and Evidence
The following sources support the role map and skill recommendations. Employer listings demonstrate current responsibilities but do not establish a universal job definition or market size.
- LinkedIn: where opportunity is emerging as work changes for broad AI hiring and AI-literacy signals.
- Singtel: Lead, AI and Agent Operations for a primary example of production responsibility, evaluation, SLOs, incidents, governance, and reporting.
- World Economic Forum: AI Agents in Action for authorization, auditability, enforceability, and operational oversight.
- NIST AI RMF Core for role clarity, production monitoring, human oversight, response, recovery, and continual improvement.
- Anthropic: Demystifying evals for AI agents for multi-turn evaluation and lifecycle testing.
- OpenTelemetry: AI agent observability for evolving semantic conventions and interoperable telemetry.
- Google SRE: production services best practices for SLO and error-budget foundations.
Continue the learning path
Frequently Asked Questions
What is an AI Agent Operations Engineer?
An AI Agent Operations Engineer operates production AI agents across monitoring, evaluation, incidents, change, governance, human escalation, cost, and continual improvement. The exact title varies, but the responsibility is dependable and controlled operation after deployment.
Is AgentOps the same as MLOps?
No. MLOps focuses heavily on model and data lifecycles. AgentOps adds multi-step behavior, tool calls, permissions, orchestration, state, human handoffs, task outcomes, and operational control of delegated action. The two disciplines often overlap.
Do I need a machine-learning degree?
Not always. Current roles vary widely. Strong candidates may come from SRE, DevOps, QA, ML engineering, security, support operations, governance, or domain operations. Technical engineer roles usually require hands-on systems and scripting ability, but not foundation-model research.
Which programming language should I learn for AgentOps?
Python is a practical first choice because it is common in AI systems, evaluation, data analysis, and automation. Also learn APIs, SQL, shell basics, Git, and the language used by your target organization's services.
What should an AgentOps portfolio include?
Include an observable tool-using agent, an evaluation and release gate, an incident simulation with recovery, and an authorization or human-oversight design. Show architecture, telemetry, tests, runbooks, decisions, and limitations.
Which metrics matter most?
Use a balanced set covering reliability, task outcomes, agent behavior, human oversight, safety, cost, and learning. Pair performance goals with guardrails so that optimizing speed or automation does not quietly increase harmful outcomes.
Can a business operations professional move into AgentOps?
Yes, especially when they bring deep workflow knowledge, exception handling, and outcome measurement. To target engineer roles, add scripting, APIs, telemetry, version control, and hands-on debugging. For operations lead roles, domain judgment and process design may be equally important.
Is AI Agent Operations a stable career?
The exact title is not yet standardized, so it may change. The underlying work is durable: deployed agents need monitoring, evaluation, incident response, authorization, human oversight, and improvement. Build around those responsibilities rather than one label.
How can I get experience without an AgentOps job?
Add agent-specific operations to your current work or a sandbox project. Instrument a narrow agent, build evaluations, inject failures, create a runbook, add a human gate, and publish a sanitized decision memo. Evidence of operational judgment can bridge the title gap.
Your Next Step
Choose one narrow agent workflow and make it operable. Instrument the journey, define success, build an evaluation set, inject failure, add a safe fallback, and write the decision record. That single complete loop will teach more than another month of passive tool tutorials.
Then compare your evidence with current job descriptions. Keep the responsibilities that repeat, ignore inflated labels, and build the missing proof one artifact at a time.

